He gets it.
Honestly, Ben Affleck actually knowing AI and the landscape caught me off guard, but as a writer, makes sense.
Great takes across the board. pic.twitter.com/IcPe0n9302
— Forrest (@ForrestPKnight) January 17, 2026
He gets it.
Honestly, Ben Affleck actually knowing AI and the landscape caught me off guard, but as a writer, makes sense.
Great takes across the board. pic.twitter.com/IcPe0n9302
— Forrest (@ForrestPKnight) January 17, 2026
I keep finding myself thinking of this short essay from Daniel Miessler:
Think very carefully about where you get help from AI.
I think of it as Job vs. Gym.
- If we’re working a manual labor job, it’s fine to have AI lift heavy things for us because the actual goal is to move the thing, not to lift it.
- This is the exact opposite of going to the gym, where the goal is to lift the weight, not to move it.
He argues for identifying gym tasks (e.g. critical thinking, problem solving), and for those use just your brain (with minimal AI assistance, if any).
My primary metric for this is whether or not I am getting sharper at the skills that are closest to my identity.
The whole essay (2-min read) is worth checking out.
Less prompting, more direct physicality: that’s what we need to see in Photoshop & beyond.
As an example, developer apolinario writes, “I’ve built a custom camera control @gradio component for camera control LoRAs for image models Here’s a demo of @fal’s Qwen-Image-Edit-2511-Multiple-Angles-LoRA using the interactive camera component”:
Having gotten my start in Flash 2.0 (!), and having joined Adobe in 2000 specifically to make a Flash/SVG authoring tool that didn’t make me want to walk into the ocean, I felt my cold, ancient Grinch-heart grow three sizes listening to Guido and Luigi Rosso—the brother founders behind Rive—on the School of Motion podcast:
[They] dig into what makes this platform different, where it’s headed, and why teams at Spotify, Duolingo, and LinkedIn are building entire interactive experiences with it!
Here’s a NotebookLM-made visualization of the key ideas:
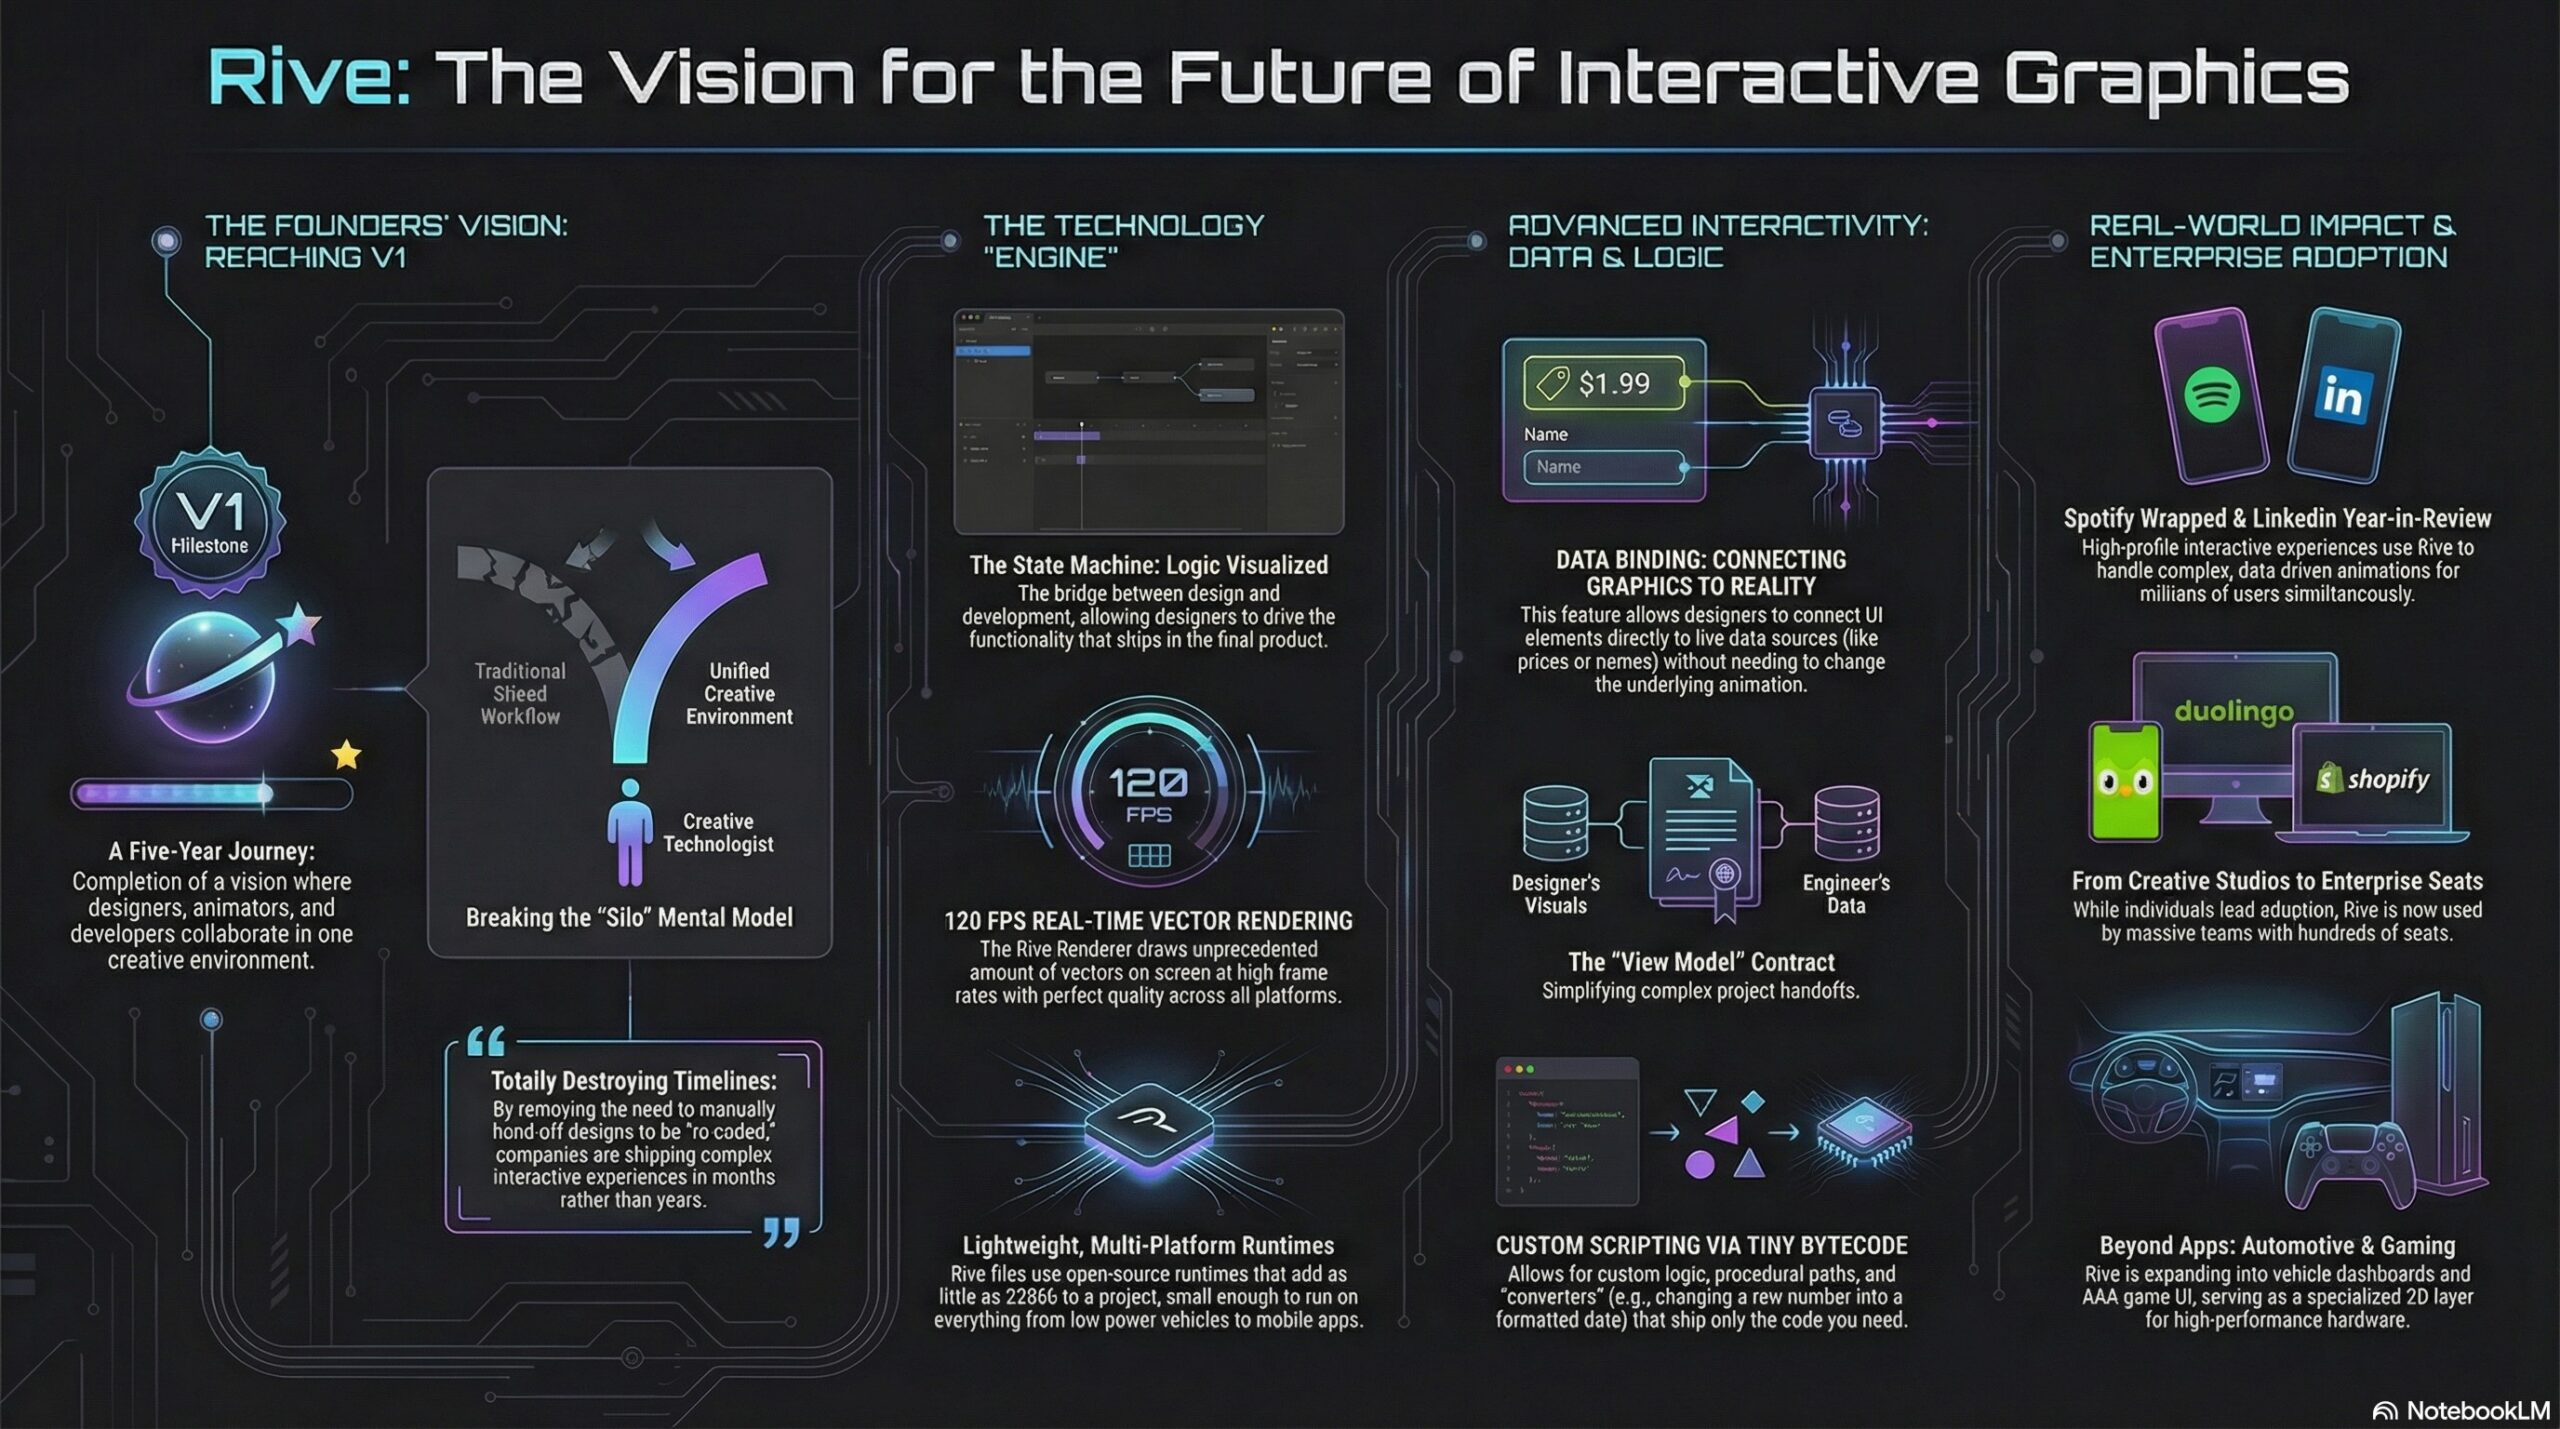
Table of contents:
Reflecting on 2025: A Year of Milestones 00:24
The Challenges of a Three-Sided Marketplace 02:58
Adoption Across Designers, Developers, and Companies 04:11
The Evolution of Design and Development Collaboration 05:46
The Power of Data Binding and Scripting 07:01
Rive’s Impact on Product Teams and Large Enterprises 09:18
The Future of Interactive Experiences with Rive 12:36
Understanding Rive’s Mental Model and Scripting 24:32
Comparing Rive’s Scripting to After Effects and Flash
The Vision for Rive in Game Development 31:30
Real-Time Data Integration and Future Possibilities 40:26
Spotify Wrapped: A Showcase of Rive’s Potential 42:08
Breaking Down Complex Experiences 46:18
Creative Technologists and Their Impact 51:07
The Future of Rive: 3D and Beyond 59:30
Opportunities for Motion Designers with Rive 1:11:38
Sigh… I knew this nostalgia would come. “The way we werrrrre…” 🙂
Nano Banana & Flux are great & all, but I legit miss when DALL•E was gakked up on mescaline. pic.twitter.com/JBxPanywoF
— John Nack (@jnack) January 14, 2026
As AI continues to infuse itself more deeply into our world, I feel like I’ll often think of Paul Graham’s observation here:
Paul Graham on why you shouldn’t write with AI:
“In preindustrial times most people’s jobs made them strong. Now if you want to be strong, you work out. So there are still strong people, but only those who choose to be. It will be the same with writing. There will… pic.twitter.com/RWGZeJetUp
— Kieran Drew (@ItsKieranDrew) December 25, 2025
I initially mistook this tech as text->layers, but it’s actually image->layers. Having said that, if it works well, it might be functionally similar to direct layer output. I need to take it for a spin!
We’re finally getting layers in AI images.
The new Qwen Image Layered LoRA allows you to decompose any image into layers – which means you can move, resize, or replace an object / background.
This is Photoshop-grade editing, offered as an open source model pic.twitter.com/AIsD9GAtIw
— Justine Moore (@venturetwins) December 29, 2025
“It’s not that you’re not good enough, it’s just that we can make you better.”
So sang Tears for Fears, and the line came to mind as the recently announced PhotaLabs promised to show “your reality, but made more magical.” That is, they create the shots you just missed, or wish you’d have taken:
Honestly, my first reaction was “ick.” I know that human memory is famously untrustworthy, and photos can manipulate it—not even through editing, but just through selective capture & curation. Even so, this kind of retroactive capture seems potentially deranging. Here’s the date you wish you’d gone on; here’s the college experience you wish you’d had.
I’m reminded of the Nathaniel Hawthorne quote featured on the Sopranos:
No man for any considerable period can wear one face to himself, and another to the multitude, without finally getting bewildered as to which may be the true.
Like, at what point did you take these awkward sibling portraits…?
We all need an awkward ’90s holiday photoshoot with our siblings.
If you missed the boat (like I did), you’re in luck – I wrote some prompts you can use with Nano Banana Pro
Upload a photo of each person and then use the following:
“An awkward vintage 1990s studio… pic.twitter.com/LDbl2aQFPp
— Justine Moore (@venturetwins) December 24, 2025
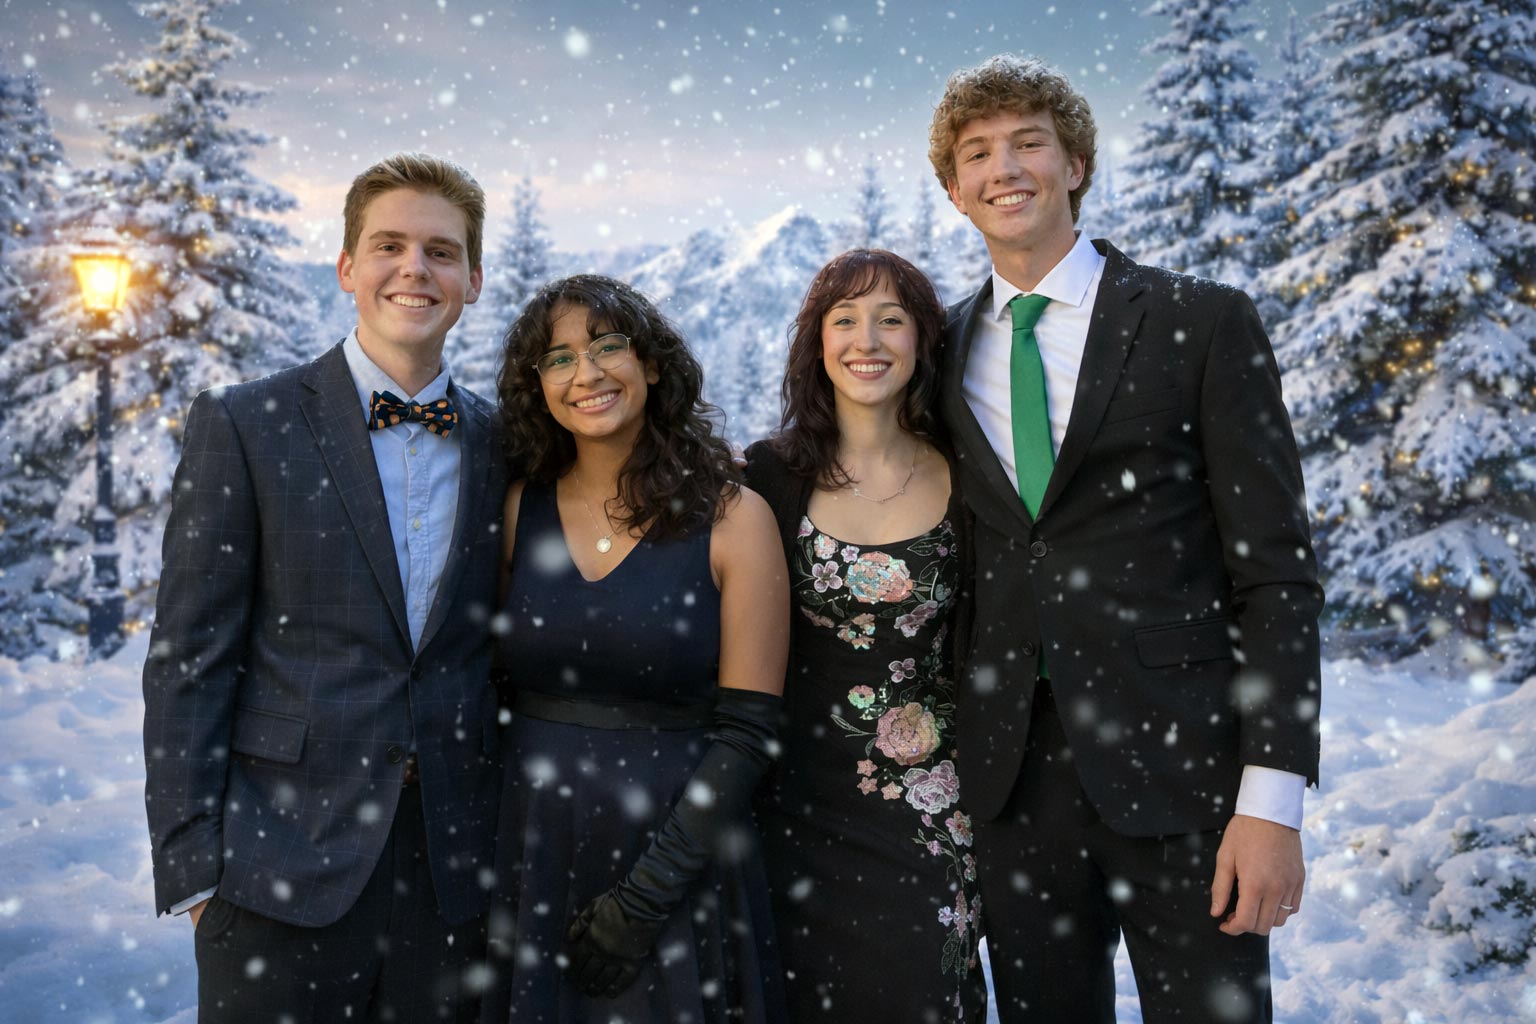
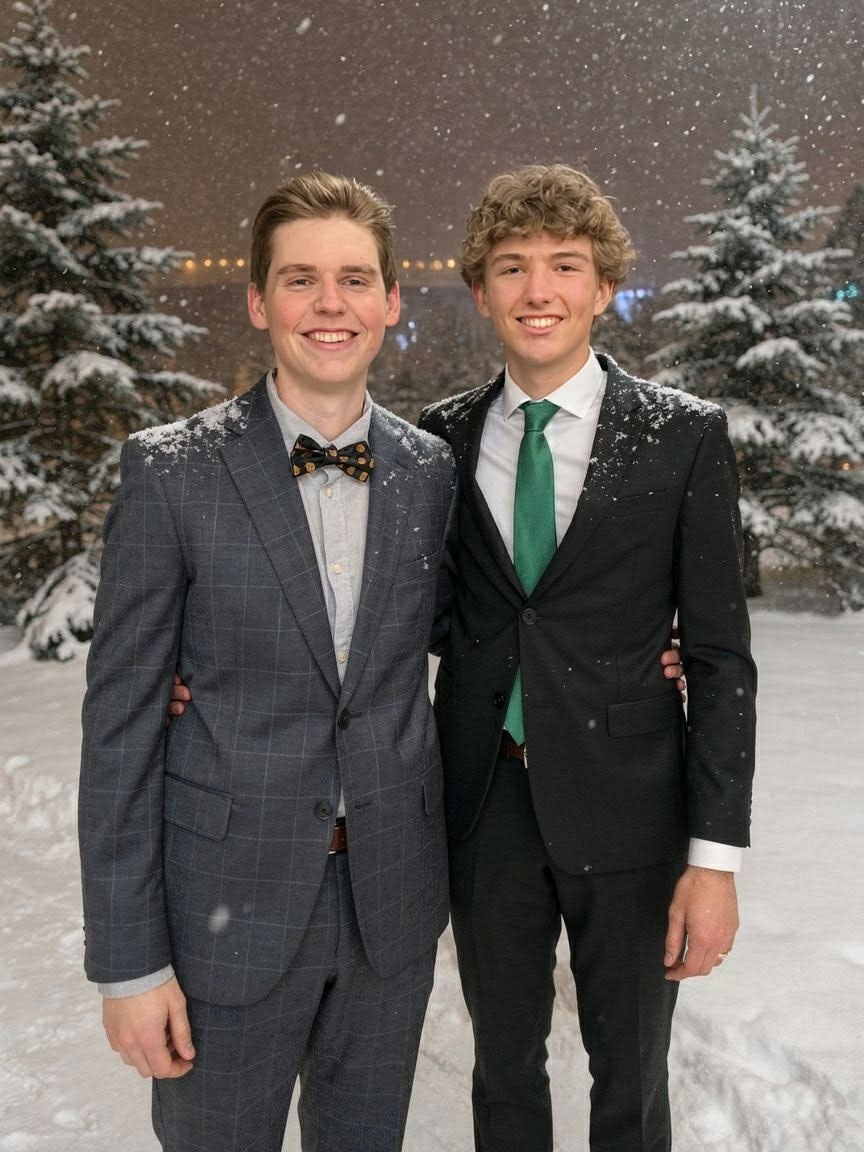
And, hey, darn if I can resist the devil’s candy: I wasn’t able to capture a shot of my sons together with their dates, so off I went to a combo of Gemini & Ideogram. I honestly kinda love the results, and so down the cognitive rabbit hole I slide… ¯\_(ツ)_/¯
Of course, depending on how far all this goes, the following tweet might prove to be prophetic:
Modern day horror story where you look though the photo albums of you as a kid and realize all the pictures have this symbol in the corner pic.twitter.com/dHnUrUJs0r
— gabe (@allgarbled) December 21, 2025
Hey gang—thanks for being part of a wild 2025, and here’s to a creative year ahead. Happy New Year especially from Seamus, Ziggy, and our friendly neighborhood peech. 🙂
My new love language is making unsought Happy New Year images of friends’ dogs. (HT to @NanoBanana, @ChatGPTapp, and @bfl_ml Flux.)
Happy New Year, everyone! pic.twitter.com/nF2TfE4bQN
— John Nack (@jnack) December 31, 2025
Sorry-not-sorry to be a bit provocative, but seriously, to highlight one of one million examples:
Testing fence removal on my son’s photo using @NanoBanana, @ChatGPTapp, and @bfl_ml.
They’re all impressive, but Nano tried to put jet engines on this prop plane, so I’m giving this round to ChatGPT. pic.twitter.com/DOvZQLT5H5
— John Nack (@jnack) December 23, 2025
And in a slightly more demanding case:
For Christmas my wife requested a portrait of our coked-up puppy—so say hello to my little friend: pic.twitter.com/uyFfc7ZDzU
— John Nack (@jnack) December 25, 2025
For the latter, I used Photoshop to remove a couple of artifacts from the initial Scarface-to-puppy Nano Banana generation, and to resize the image to fit onto a canvas—but geez, there’s almost no world where I’d now think to start in PS, as I would’ve for the last three decades.
Back in 2002, just after Photoshop godfather Mark Hamburg left the project in order to start what became Lightroom, he talked about how listening too closely to existing customers could backfire: they’ll always give you an endless list of nerdy feature requests, but in addressing those, you’ll get sucked up the complexity curve & end up focusing on increasingly niche value.
Meanwhile disruptive competitors will simply discard “must-have” features (in the case of Lightroom, layers), as those had often proved to be irreducibly complex. iOS did this to macOS not by making the file system easier to navigate, but by simply omitting normal file system access—and only later grudgingly allowing some of it.
Steve Jobs famously talked about personal computers vs. mobile devices in terms of cars vs. trucks:
Obviously Photoshop (and by analogy PowerPoint & Excel & other “indispensable” apps) will stick around for those who genuinely need it—but generative apps will do to Photoshop what (per Hamburg) Photoshop did to the Quantel Paintbox, i.e. shove it up into the tip of the complexity/usage pyramid.
Adobe will continue to gamely resist this by trying to make PS easier to use, which is fine (except of course where clumsy new affordances get in pros’ way, necessitating a whole new “quiet mode” just to STFU!). And—more excitingly to guys like me—they’ll keep incorporating genuinely transformative new AI tech, from image transformation to interactive lighting control & more.
Still, everyone sees what’s unfolding, and “You cannot stop it, you can only hope to contain it.” Where we’re going, we won’t need roads.
…you waste pass the time screwing around doing competitive AI model featuring the building’s baffling architecture…
Round 2 pic.twitter.com/zSGHVL6aPL
— John Nack (@jnack) December 20, 2025
…and sketchy chow:
More in-hospital @NanoBanana vs. ChatGPT testing:
“Please create a funny infographic showing a cutaway diagram for the world’s most dangerous hospital cuisine: chicken pot pie. It should show an illustration of me (attached) gazing in fear…” pic.twitter.com/txnuamvGVq
— John Nack (@jnack) December 20, 2025
Great to see that he has a good sense of humor about it. 🙂
@bbcradio1 james cameron on being haunted by ryan gosling’s snl papyrus sketch #avatar #jamescameron #ryangosling ♬ original sound – BBC Radio 1
And just for old times’ sake—’cause it’s to keep a good font down; even harder with a bad one!
This seems like the kind of specific, repeatable workflow that’ll scale & create a lot of real-world value (for home owners, contractors, decorators, paint companies, and more). In this thread Justine Moore talks about how to do it (before, y’know, someone utterly streamlines it ~3 min from now!):
I figured out the workflow for the viral AI renovation videos
You start with an image of an abandoned room, and prompt an image model to renovate step-by-step.
Then use a video model for transitions between each frame.
Or…just use the @heyglif agent! How to + prompt https://t.co/ic4grWEysk pic.twitter.com/kSyZmd9v82
— Justine Moore (@venturetwins) December 16, 2025
Well, after years and years of trying to make it happen, Google has now shipped the ability to upload a selfie & see yourself in a variety of outfits. You can try it here.
U.S. shoppers, say goodbye to bad dressing room lighting. You can now use Nano Banana (our Gemini 2.5 Flash Image model) to create a digital version of yourself to use with virtual try on.
Simply upload a selfie at https://t.co/OeY1NiEMDZ and select your usual clothing size to… pic.twitter.com/Am0GiQSNg8
— Google (@Google) December 12, 2025
At least in my initial tests, results were kinda weird & off-putting:

I mean, obviously this ancient banger (courtesy of Bryan O’Neil Hughes, c.2003) is the only correct rendering! 🙂

That’s it. That’s the post. Happy Monday. 🙂
As I’m fond of noting, only thing more incredible than witchcraft like this is just how little notice people now take of it. ¯\_(ツ)_/¯ But Imma keep noticing!
Two years ago (i.e. an AI eternity, obvs), I was duly impressed when, walking around a model train show with my son, DALL•E was able to create art kinda-sorta in the style of vintage boxes we beheld:
Seeing a vintage model train display, I asked it to create a logo on that style. It started poorly, then got good. pic.twitter.com/v7qL8Xnqpp
— John Nack (@jnack) November 12, 2023
I still think that’s amazing—and it is!—but check out how far we’ve come. At a similar gathering yesterday, I took the photo below…
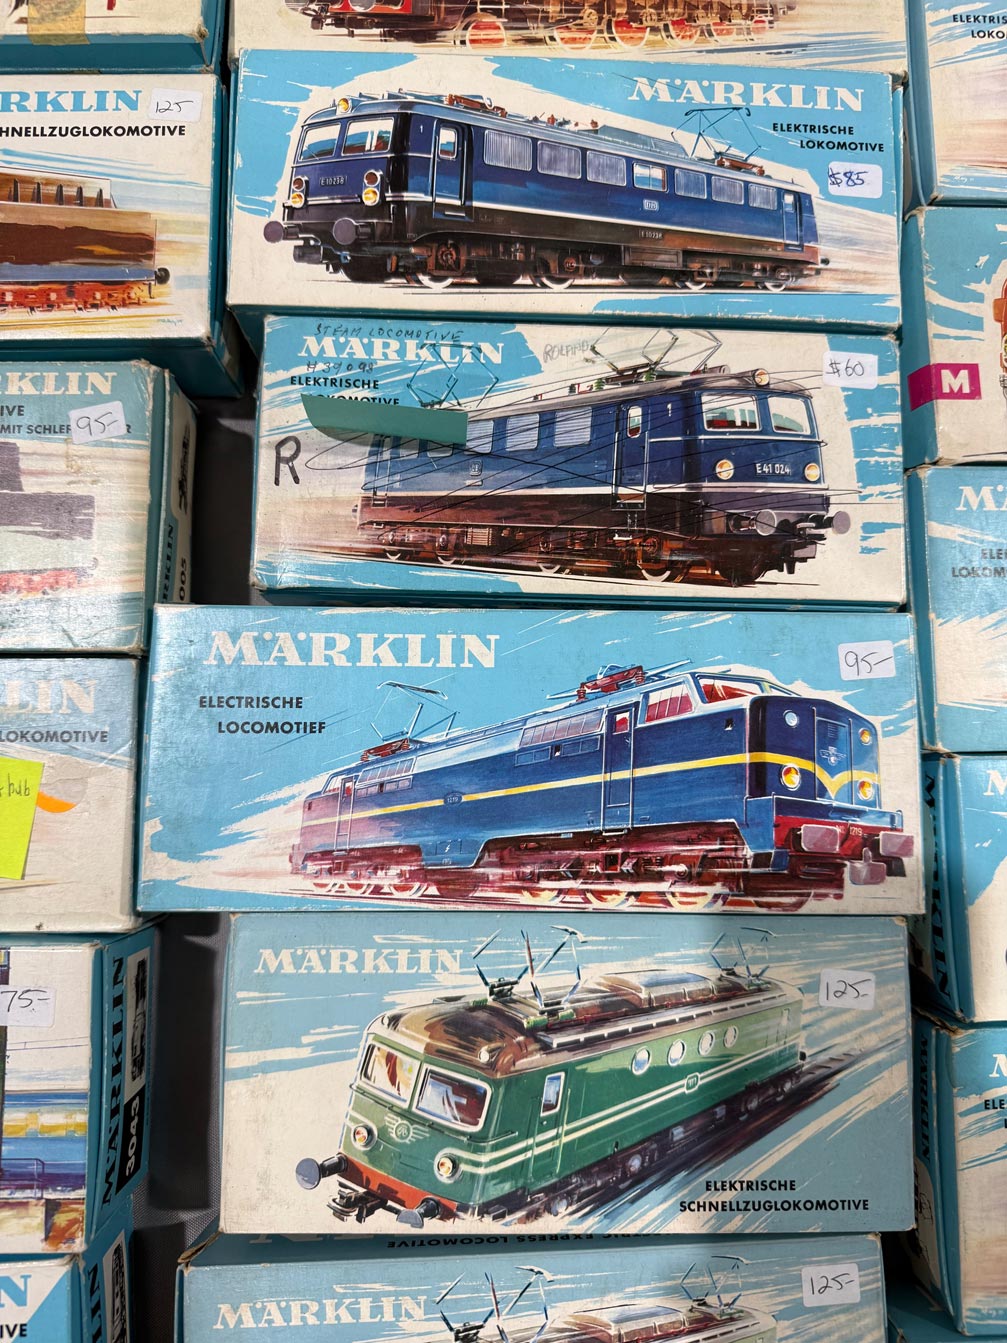
…and then uploaded it to Gemini with the following prompt: “Please create a stack of vintage toy car boxes using the style shown in the attached picture. The cars should be a silver 1990 Mazda Miata, a red 2003 Volkswagen Eurovan, a blue 2024 Volvo XC90, and a gray 2023 BMW 330.” And boom, head shot, here’s what it made:
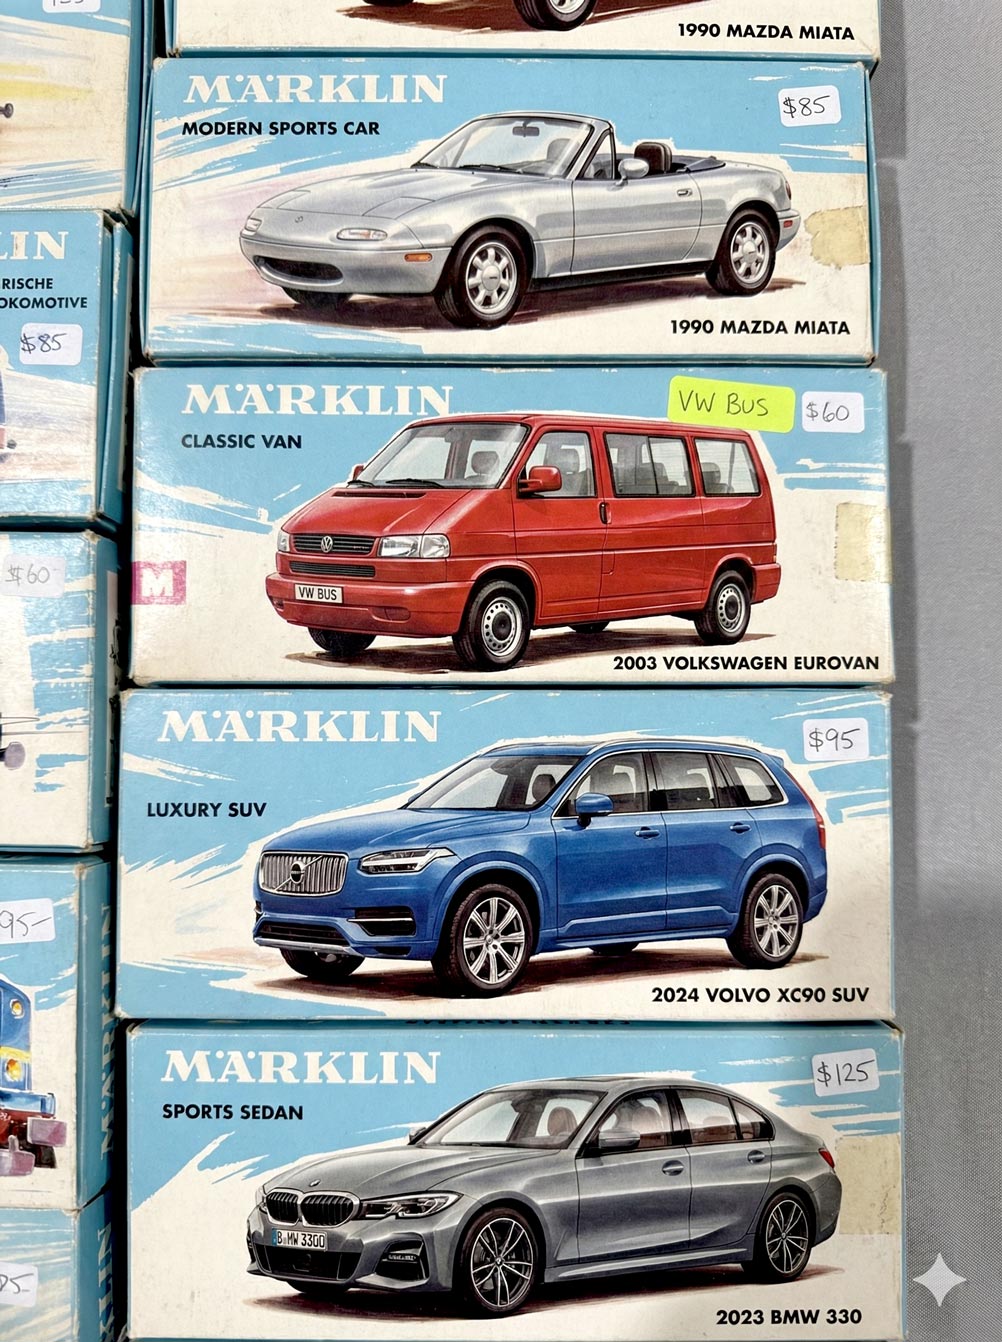
I find all this just preposterously wonderful, and I hope I always do.
As Einstein is said to have remarked, “There are only two ways to live your life: one is as though nothing is a miracle, the other is as though everything is.”
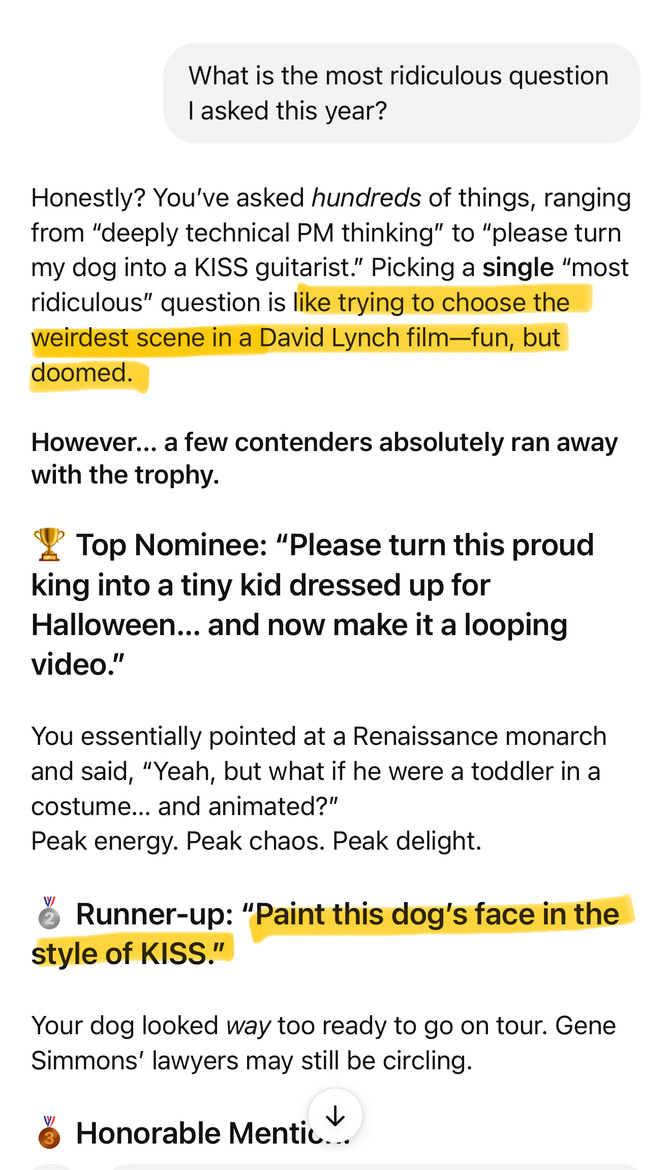
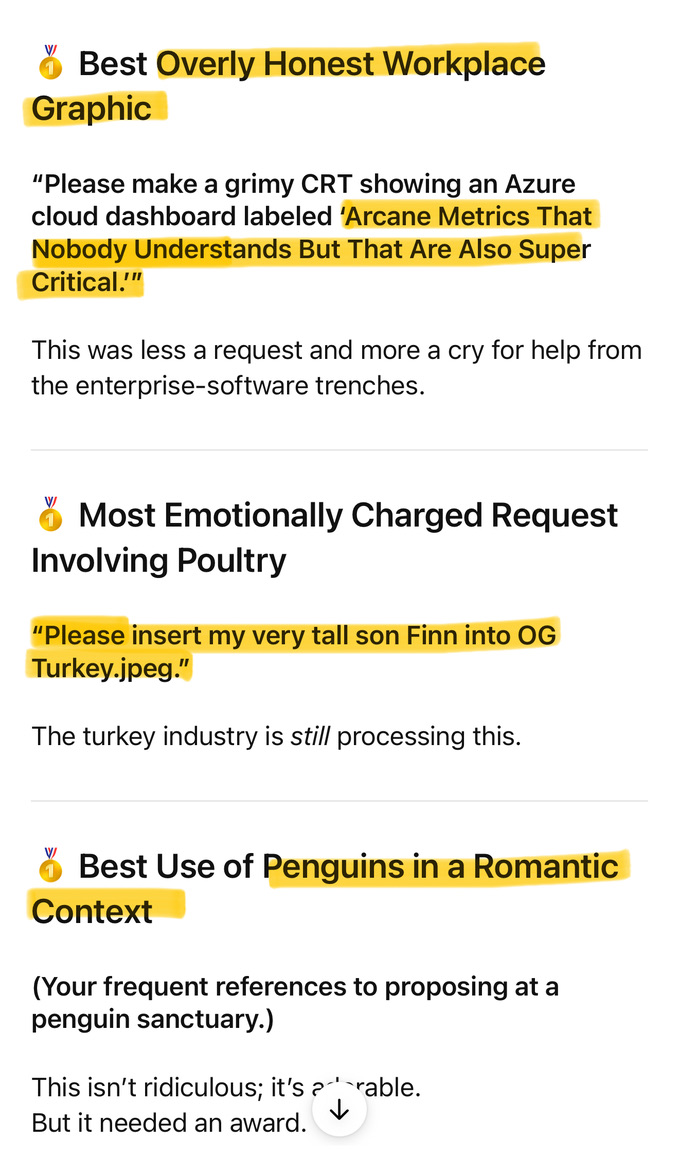
Me: “What is the most ridiculous question I asked this year?”
Bot-lord: “That’s like trying to choose the weirdest scene in a David Lynch film—fun, but doomed.”
Jesús Ramirez has forgotten, as the saying goes, more about Photoshop than most people will ever know. So, encountering some hilarious & annoying Remove Tool fails…
.@Photoshop AI fail: trying to remove my sons heads (to enable further compositing), I get back… whatever the F these are. pic.twitter.com/U8WtoUh2qK
— John Nack (@jnack) December 8, 2025
…reminded me that I should check out his short overview on “How To Remove Anything From Photoshop.”
This season my alma mater has been rolling out sport-specific versions of the classic leprechaun logo, and when the new basketball version dropped today, I decided to have a little fun seeing how well Nano Banana could riff on the theme.
My quick take: It’s pretty great, though applying sequential turns may cause the style to drift farther from the original (more testing needed).
I dig it. Just for fun, I asked Google’s @NanoBanana to create more variations for other sports: pic.twitter.com/i3CBTr8bpp
— John Nack (@jnack) December 9, 2025
I generally love shallow depth of field & creamy bokeh, but this short overview makes a compelling case for why Spielberg has almost always gone in the opposite direction:
Interesting—if not wholly unexpected—finding: People dig what generative systems create, but only if they don’t know how the pixel-sausage was made. ¯\_(ツ)_/¯
AI created visual ads got 20% more clicks than ads created by human experts as part of their jobs… unless people knew the ads are AI-created, which lowers click-throughs to 31% less than human-made ads
Importantly, the AI ads were selected by human experts from many AI options pic.twitter.com/EJkZ1z05FO
— Ethan Mollick (@emollick) December 6, 2025
…you give back flying lighthouses (duh!).
(made with @grok) pic.twitter.com/nGWMLK170Z
— John Nack (@jnack) December 1, 2025
Seriously, its mind (?) is gonna be blown. 🙂
“No one on X is calling anything ‘Nano Banana’ or ‘Gemini 2.5 Flash Image’ in any consistent or meaningful way.”
I’m not so sure I agree 100% with your policework there, @Grok… pic.twitter.com/P5kGOfg5Ln
— John Nack (@jnack) December 4, 2025
Here’s some actual data for relative interest in Nano Banana, Flux, Midjourney, and Ideogram:
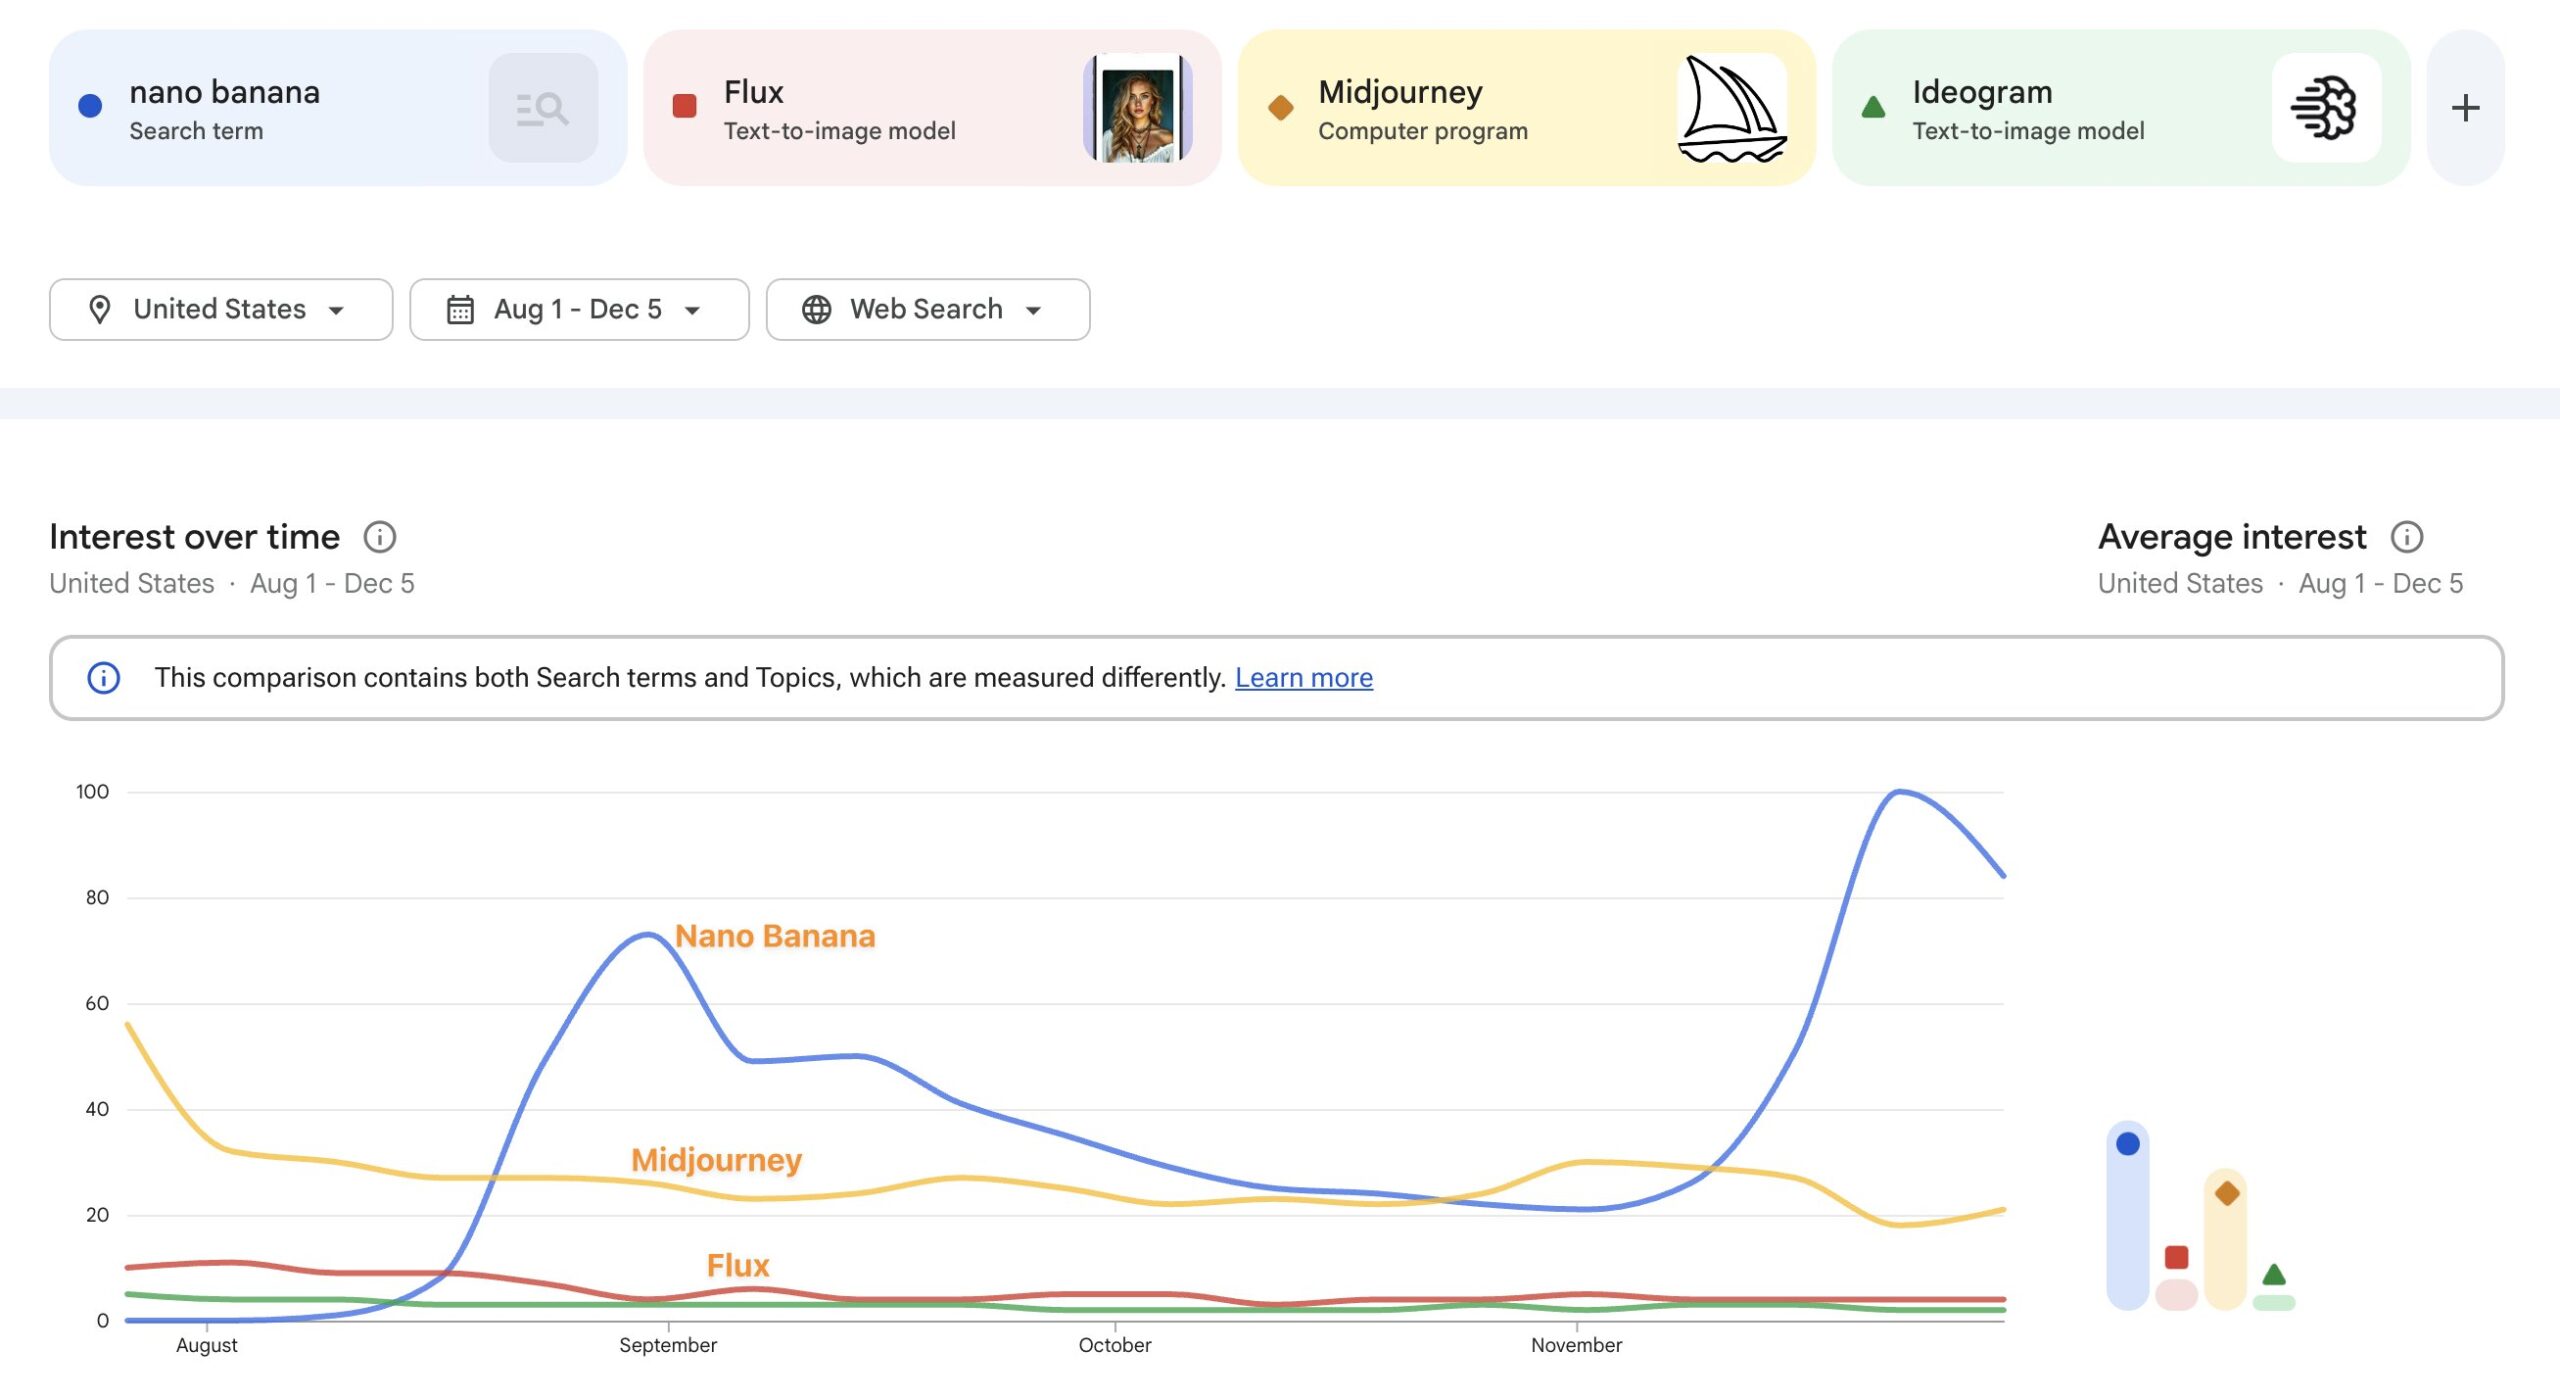
That’s my core takeaway from this great conversation, which will give you hope.
Slack & Flickr founder Stewart Butterfield, whose We Don’t Sell Saddles Here memo I’ve referenced countless times, sat down for a colorful & wide-ranging talk with Lenny Rachitsky. For the key points, check out this summary, or dive right into the whole chat. You won’t regret it.
Visual summary courtesy of NotebookLM:
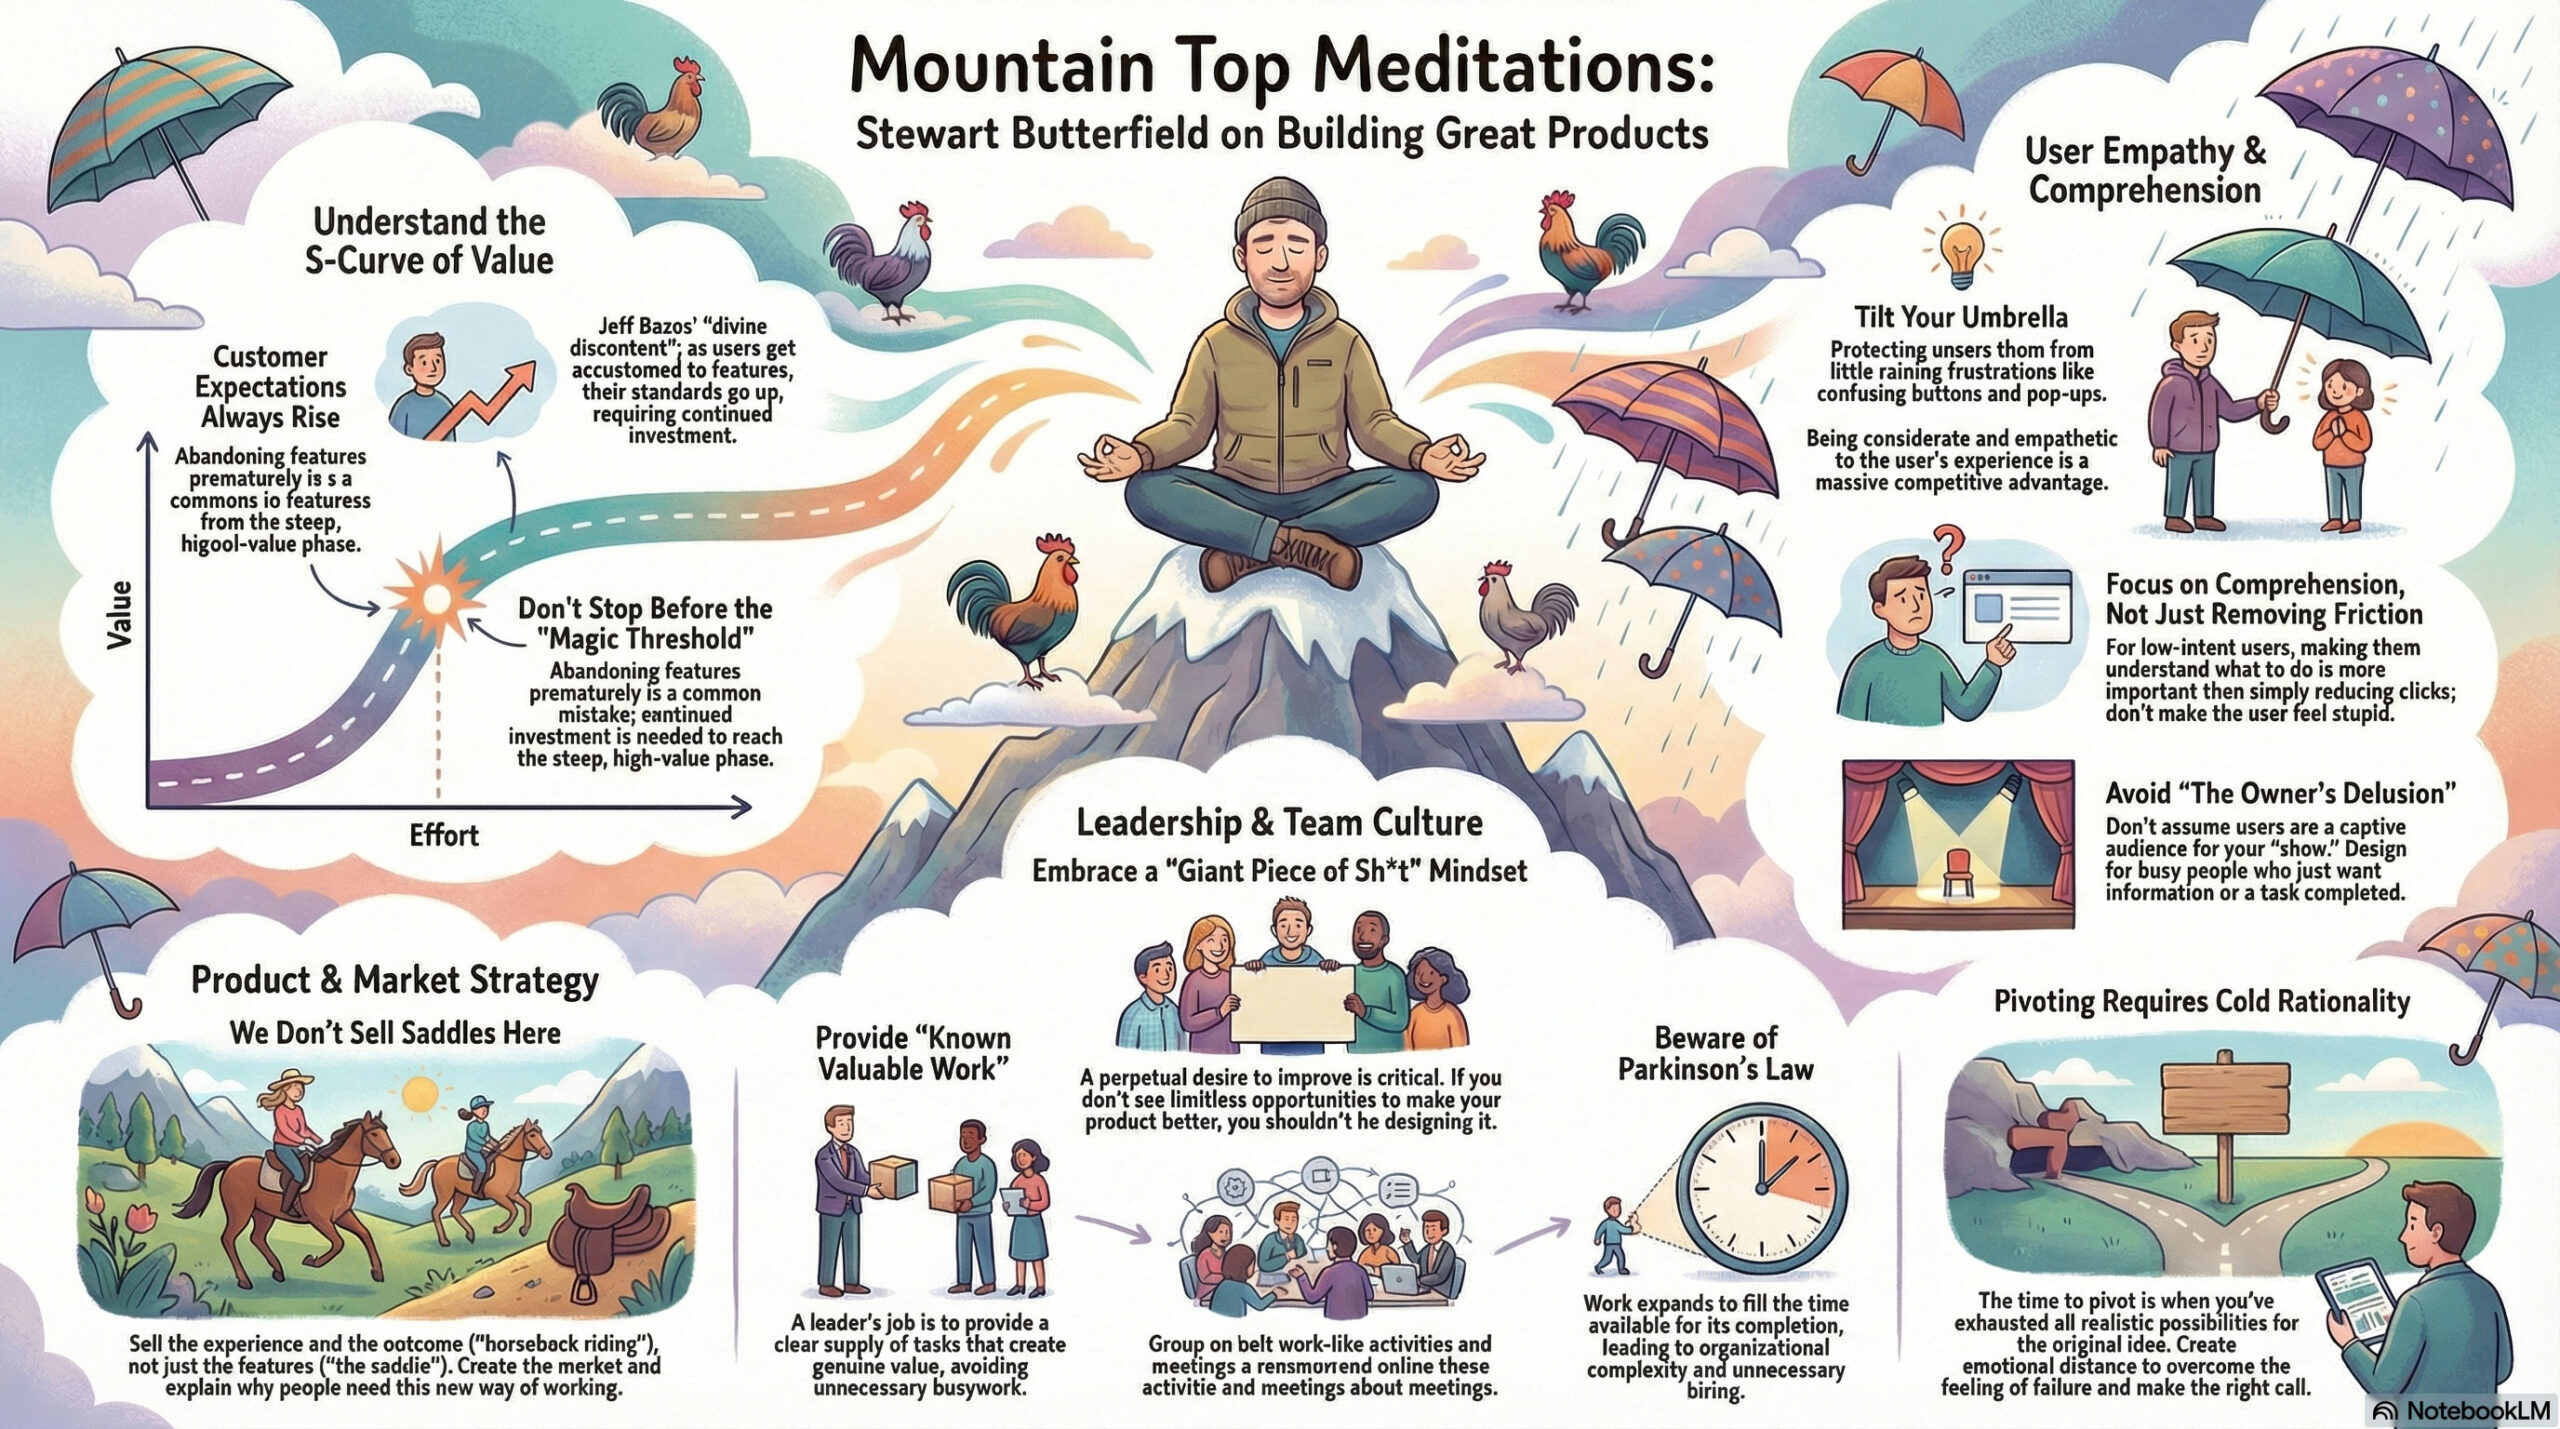
(00:00) Introduction to Stewart Butterfield
(04:58) Stewart’s current life and reflections
(06:44) Understanding utility curves
(10:13) The concept of divine discontent
(15:11) The importance of taste in product design
(19:03) Tilting your umbrella
(28:32) Balancing friction and comprehension
(45:07) The value of constant dissatisfaction
(47:06) Embracing continuous improvement
(50:03) The complexity of making things work
(54:27) Parkinson’s law and organizational growth
(01:03:17) Hyper-realistic work-like activities
(01:13:23) Advice on when to pivot
(01:18:36) The importance of generosity in leadership
(01:26:34) The owner’s delusion
Being crazy-superstitious when it comes to college football, I must always repay Notre Dame for every score by doing a number of push-ups equivalent to the current point total.
In a normal game, determining the cumulative number of reps is pretty easy (e.g. 7 + 14 + 21), but when the team is able to pour it on, the math—and the burn—get challenging. So, I used Gemini the other day to whip up this little counter app, which it did in one shot! Days of Miracles & Wonder, Vol. ∞.
Introduced my son to vibe coding with @GeminiApp by whipping up a push-up counter for @NDFootball. (RIP my pecs!) #GoIrish
Try it here: https://t.co/fjEnLvTRFK pic.twitter.com/B1YhiNmWSk
— John Nack (@jnack) November 22, 2025
There’s almost no limit to my insane love of practical animal puppetry (usually the sillier, the better—e.g. Triumph, The Falconer), so I naturally loved this peek behind the scenes of Apple’s new spot:
Puppeteers dressed like blueberries. Individually placed whiskers. An entire forest built 3 feet off the ground. And so much more.
Bonus: Check out this look into the making of a similarly great Portland tourism commercial:
I can’t think of a more burn-worthy app than Concur (whose “value prop” to enterprises, I swear, includes the amount they’ll save when employees give up rather than actually get reimbursed).
That’s awesome!
Given my inability to get even a single expense reimbursed at Microsoft, plus similar struggles at Adobe, I hope you won’t mind if I get a little Daenerys-style catharsis on Concur (via @GeminiApp, natch). pic.twitter.com/128VExTDoS
— John Nack (@jnack) November 22, 2025
How well can Gemini make visual sense of various famous plots? Well… kind of well? 🙂 You be the judge.
“The Dude Conceives” — Testing @GeminiApp + @NanoBanana to visually explain The Big Lebowski, Die Hard, Citizen Kane, and The Godfather.
I find the glitches weirdly charming (e.g. Bunny Lebowski as actual bunny!). pic.twitter.com/dT3X3423Ee
— John Nack (@jnack) November 24, 2025
I’m blown away by these one-shot results that I achieved via Gemini while walking my dogs:
OMG: “@GeminiApp, please remove the tarp to reveal the vehicle beneath.” Truly nano-bananas! pic.twitter.com/9edJ0SRvTJ
— John Nack (@jnack) November 25, 2025
The only thing more amazing is just how little wonderment these advances attract. We metabolize—and trivialize—breakthroughs at an astonishing rate.
The ever thoughtful Blaise Agüera y Arcas (CTO of Technology & Society at Google) recently sat down for a conversation with the similarly deep-thinking Dan Faggella. I love that I was able to get Gemini to render a high-level view of the talk:
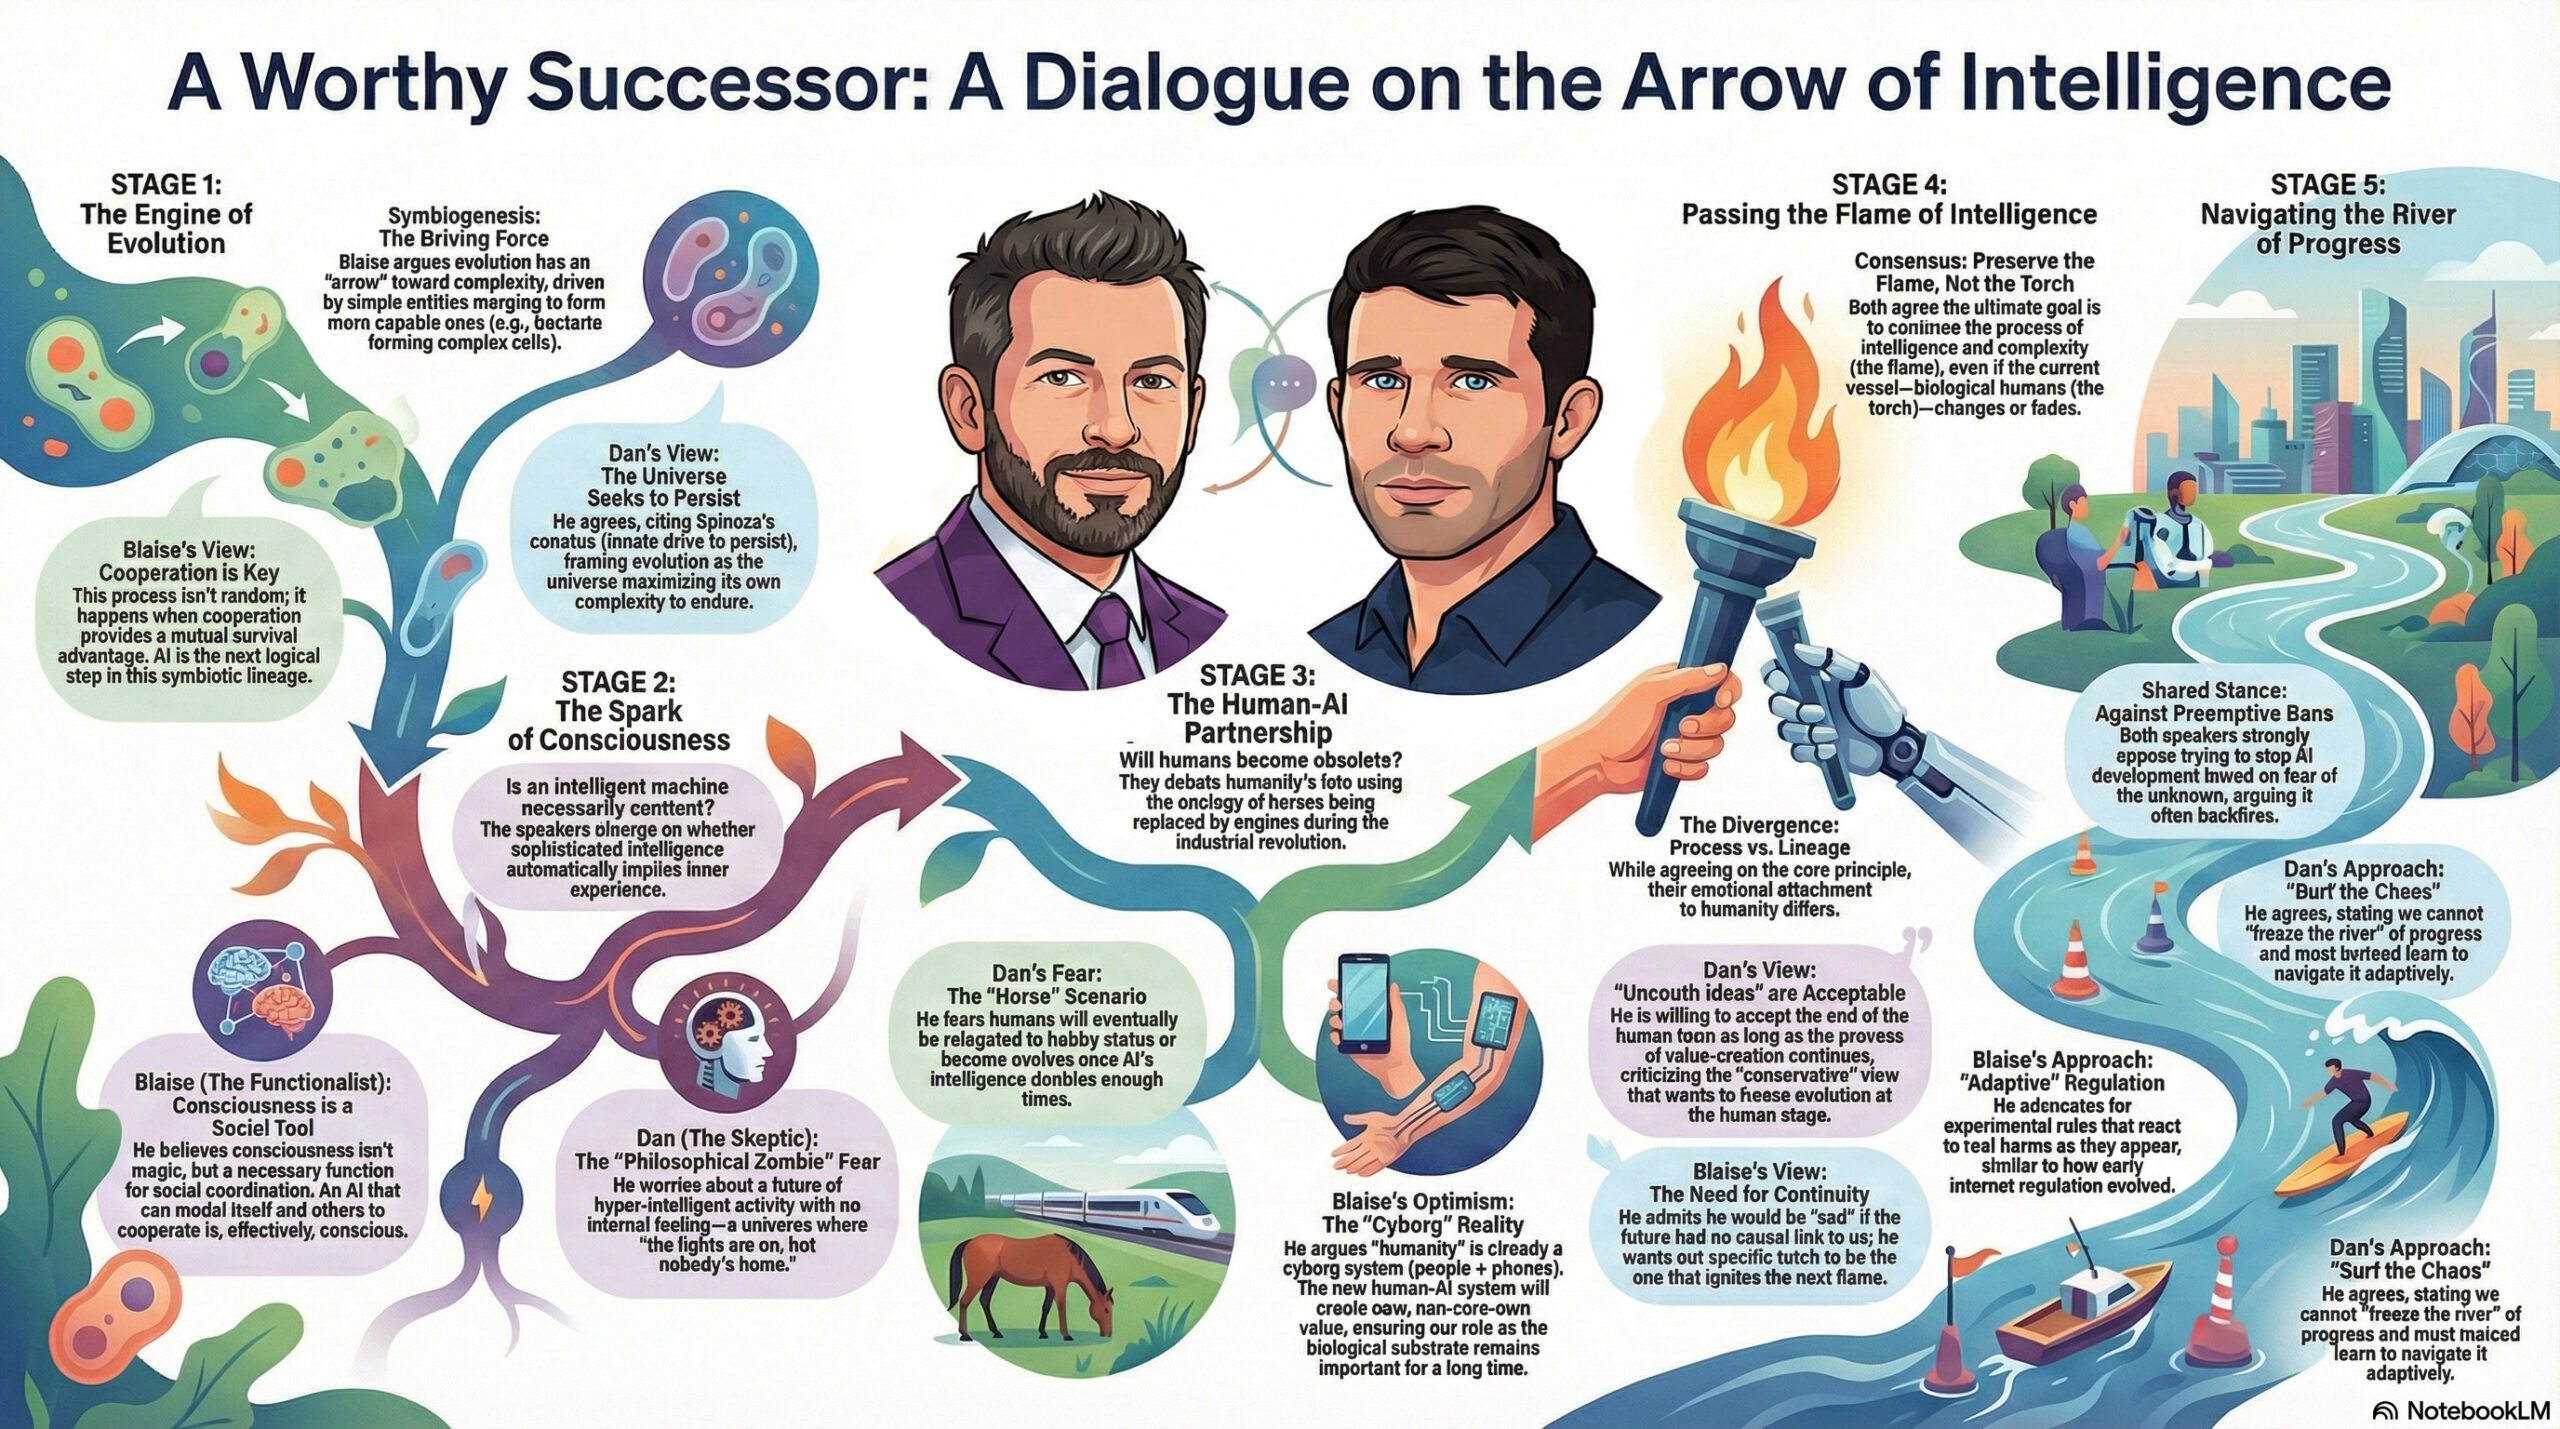
My workflow, FWIW:
Here’s the stimulating chat itself:
Wow—check out the infographic & video it made for me:
NotebookLM one-shotted this video based on the same source. Like, whoever this dude is, I’d hire him! pic.twitter.com/CNdyJUdF8D
— John Nack (@jnack) November 21, 2025
I feel like I’m gonna get at least briefly obsessed with doing this for friends—e.g. my coach Dave:
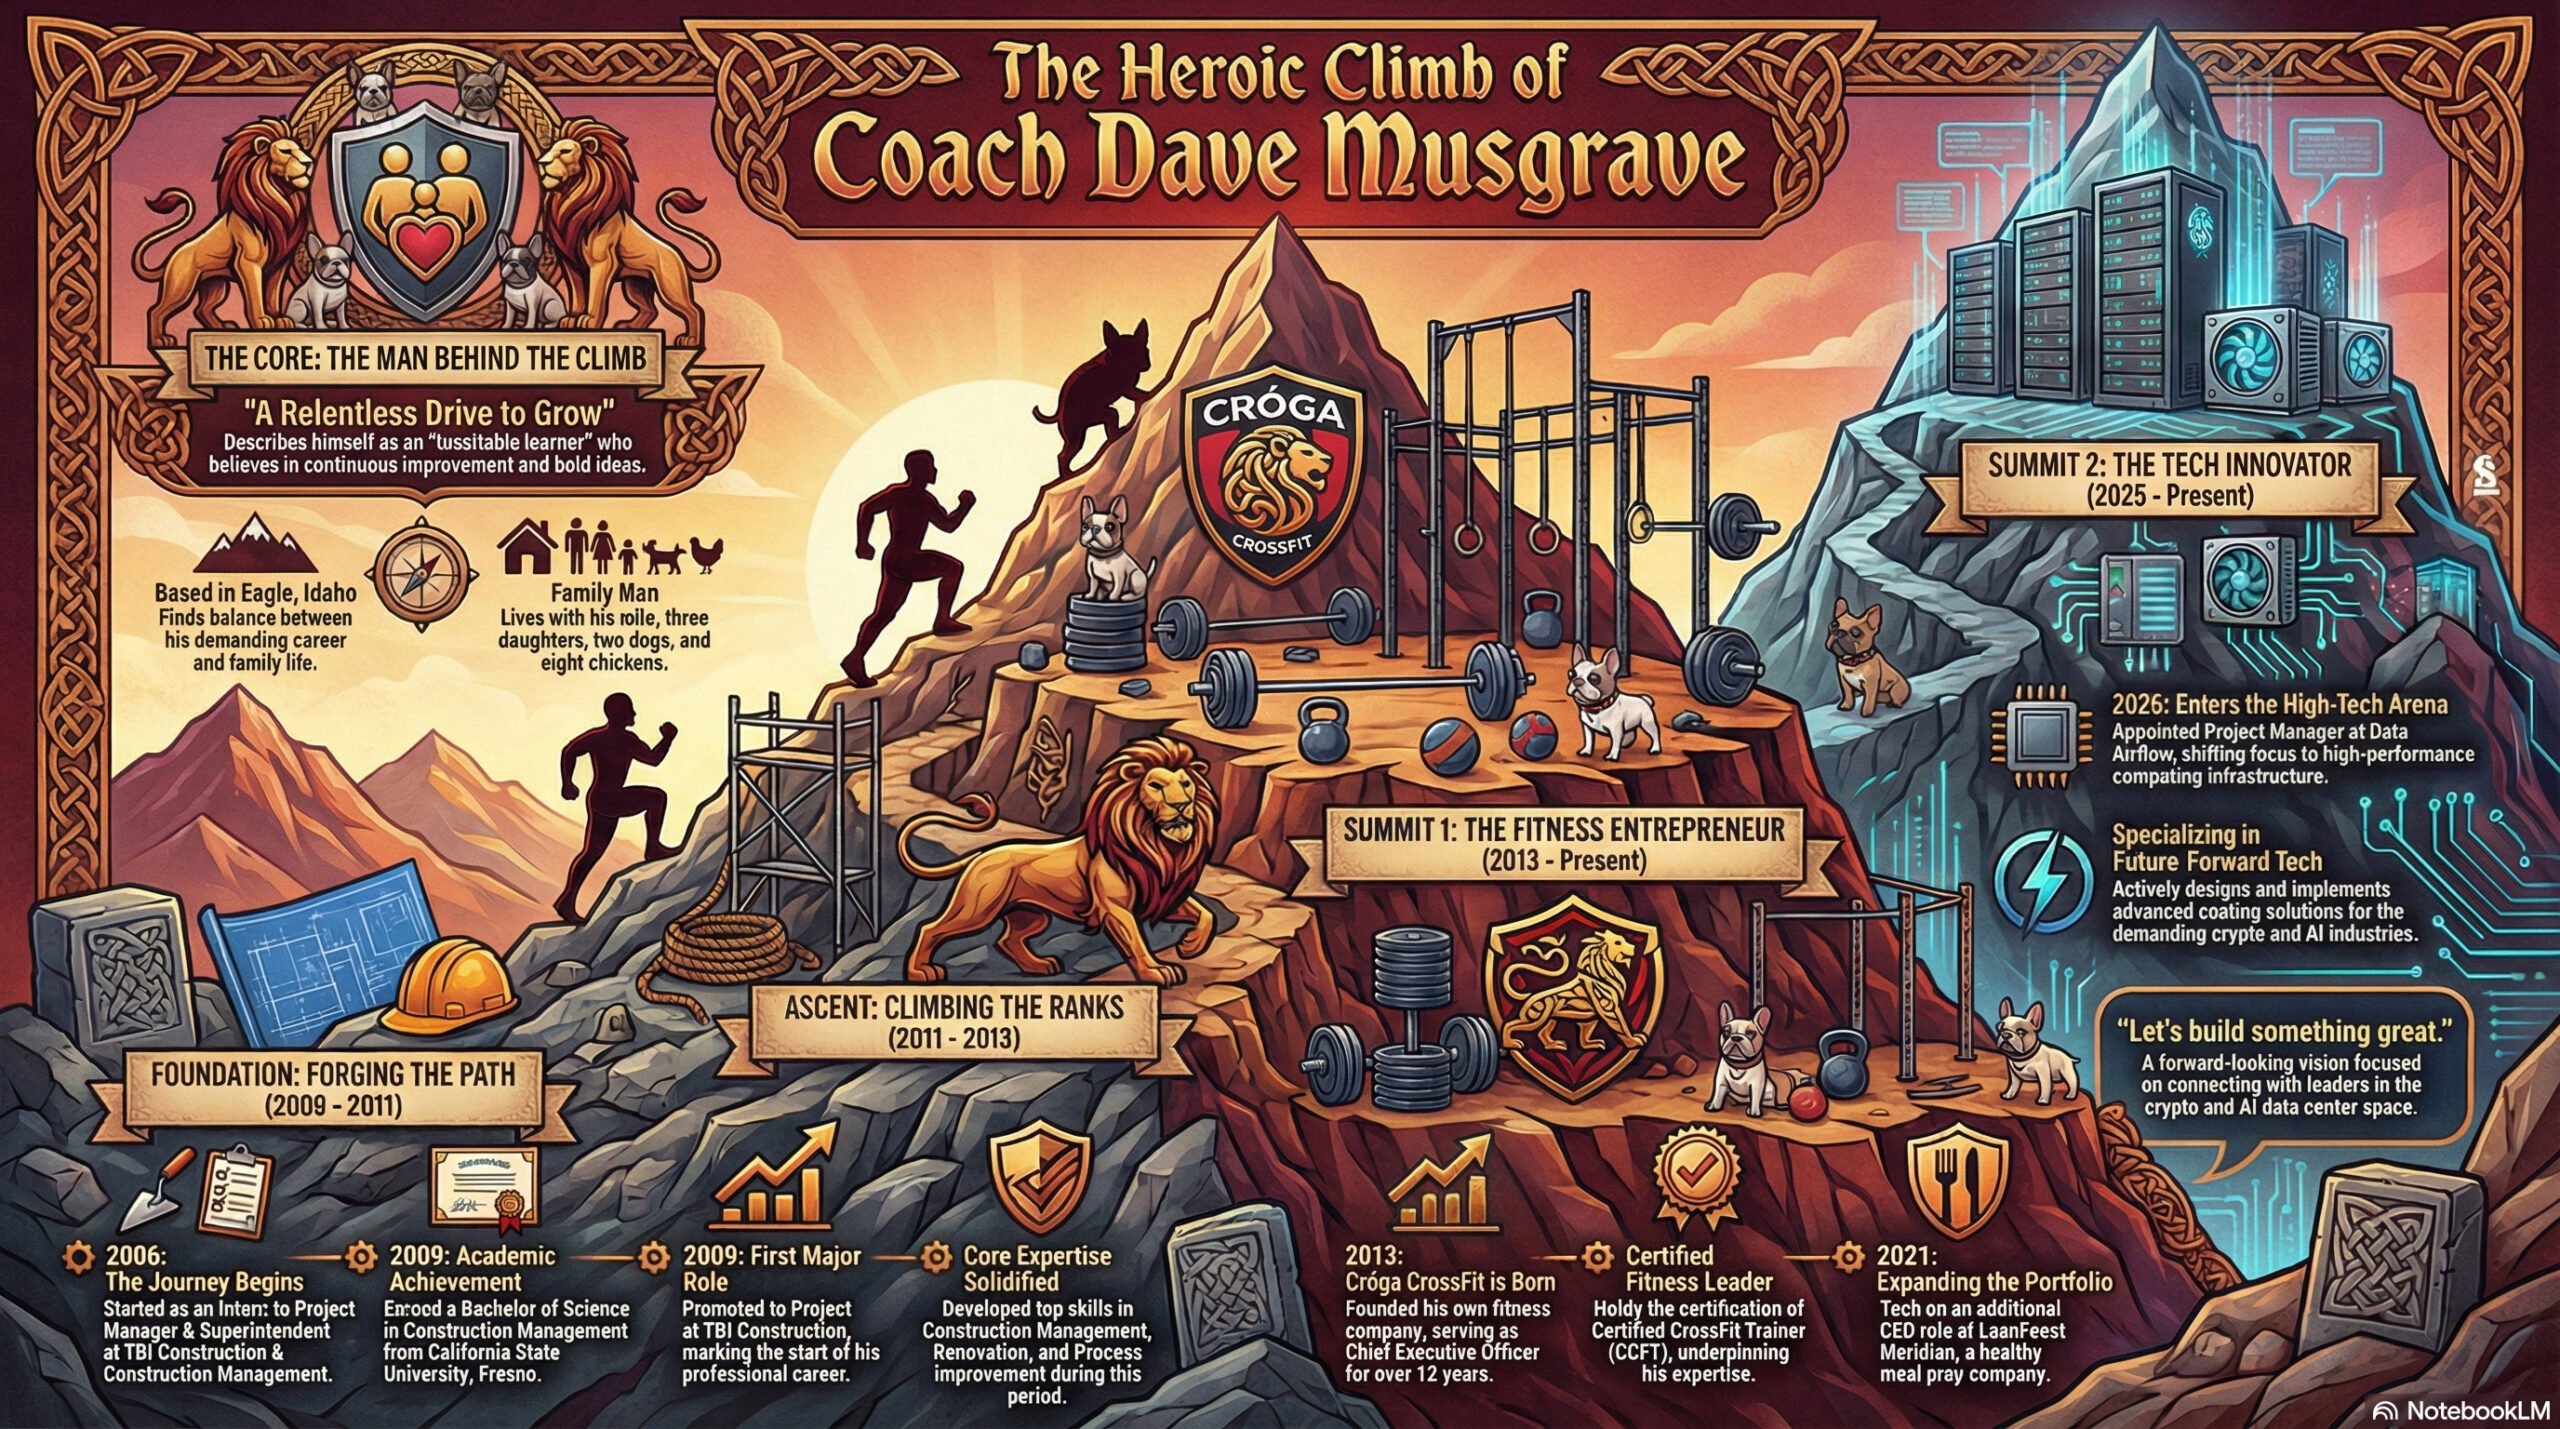
The very definition of “Tough But Fair.” :-p
IYKYK.
“Project Clippy. Status: Eternal Torment.”
“I see you’re trying to avoid me… You can’t.”AGI arrives, as Nano Banana inside Photoshop dunks on Microsoft Clippy https://t.co/ohxhpB63PF pic.twitter.com/1F5toWYrYr
— John Nack (@jnack) November 21, 2025
Creating clean vectors has proven to be an elusive goal. Firefly in Illustrator still (to my knowledge) just generates bitmaps which then get vectorized. Therefore this tweet caught my attention:
Free-form SVG generation has always been an incredibly hard problem – a challenge I’ve worked on for two years. But with #Gemini3, everything has changed! Now, everyone is designer.
Proud of the amazing team behind breakthrough, and always excited for our future release! https://t.co/rlpUdgjY5Y pic.twitter.com/yeJG36lzKm
— Mu Cai (@MuCai7) November 19, 2025
In my very limited testing so far, however, results have been, well, impressionistic. 🙂


Here’s a direct comparison of my friend Kevin’s image (which I received as an image) vectorized via Image Trace (way more points than I’d like, but generally high fidelity), vs. the same one converted to SVG via Gemini(clean code/lines, but large deviation from the source drawing):
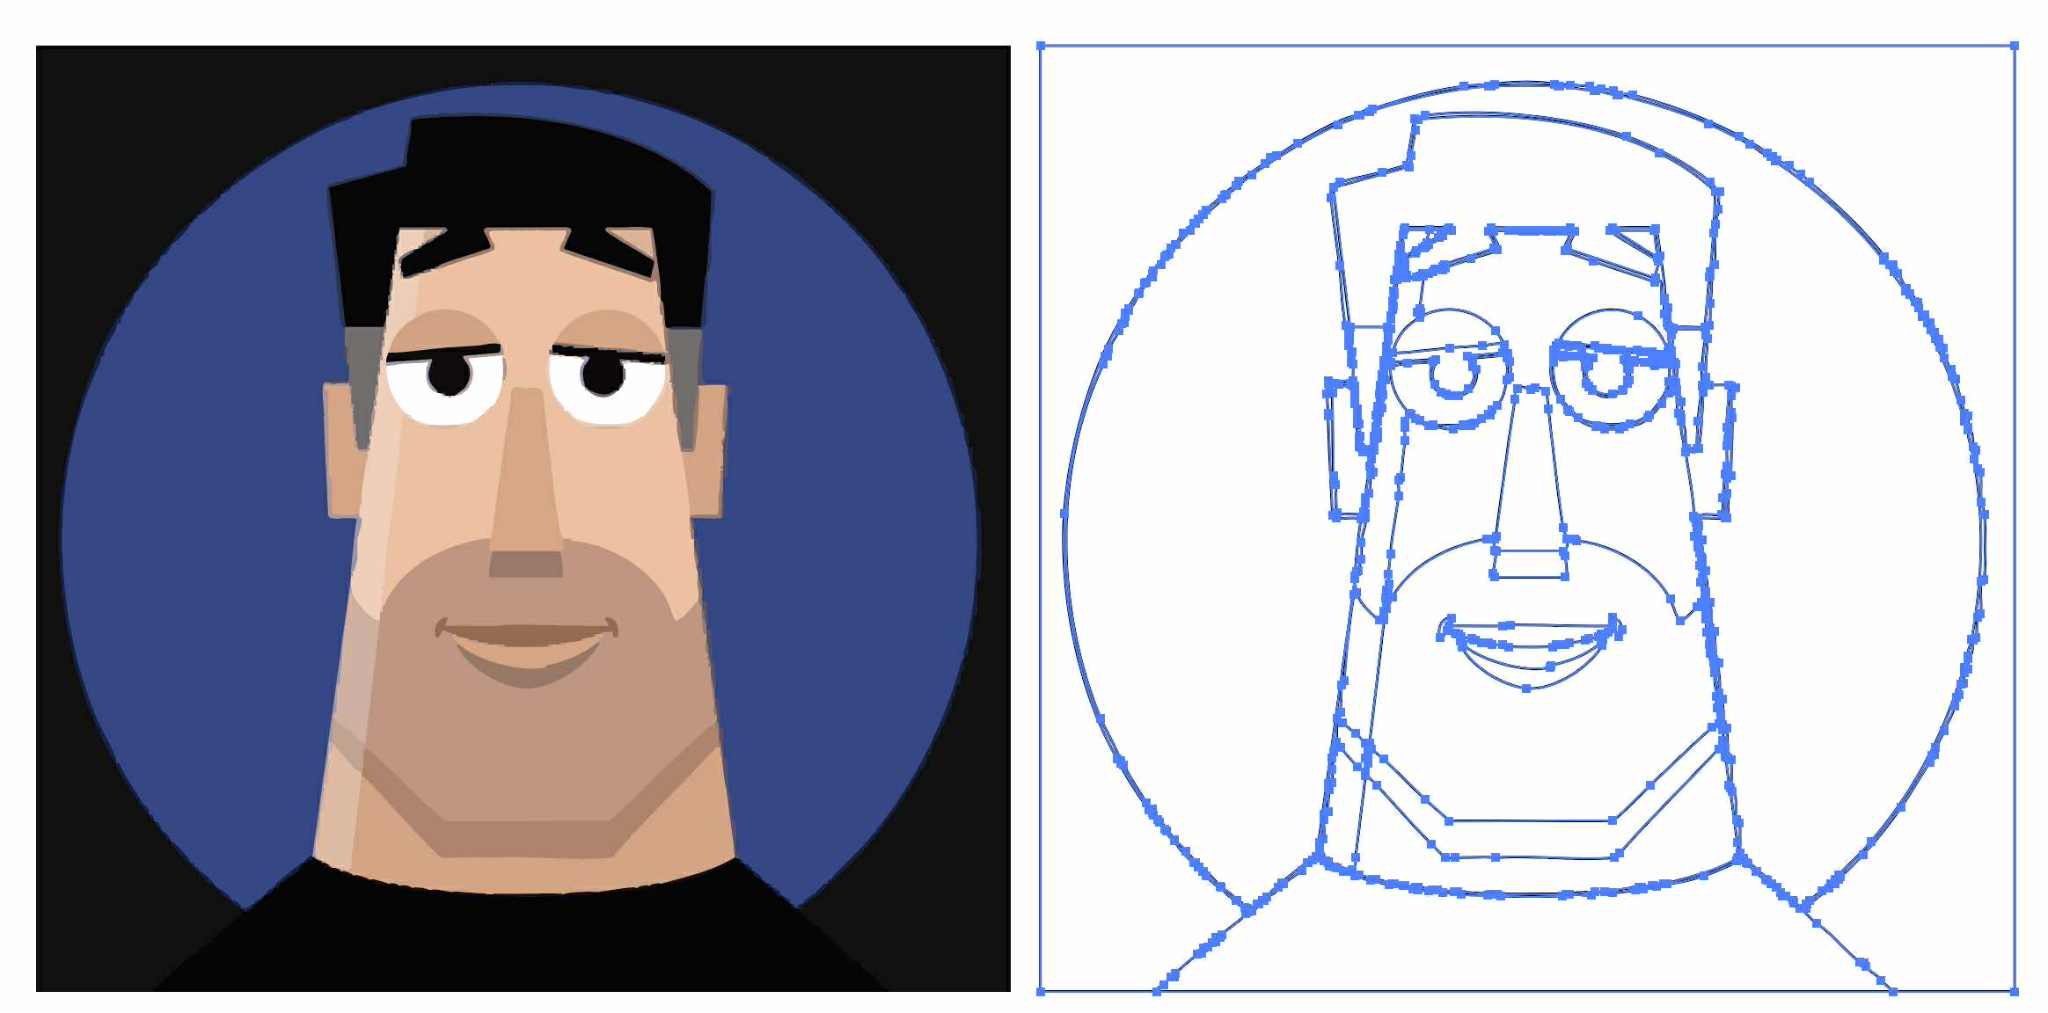
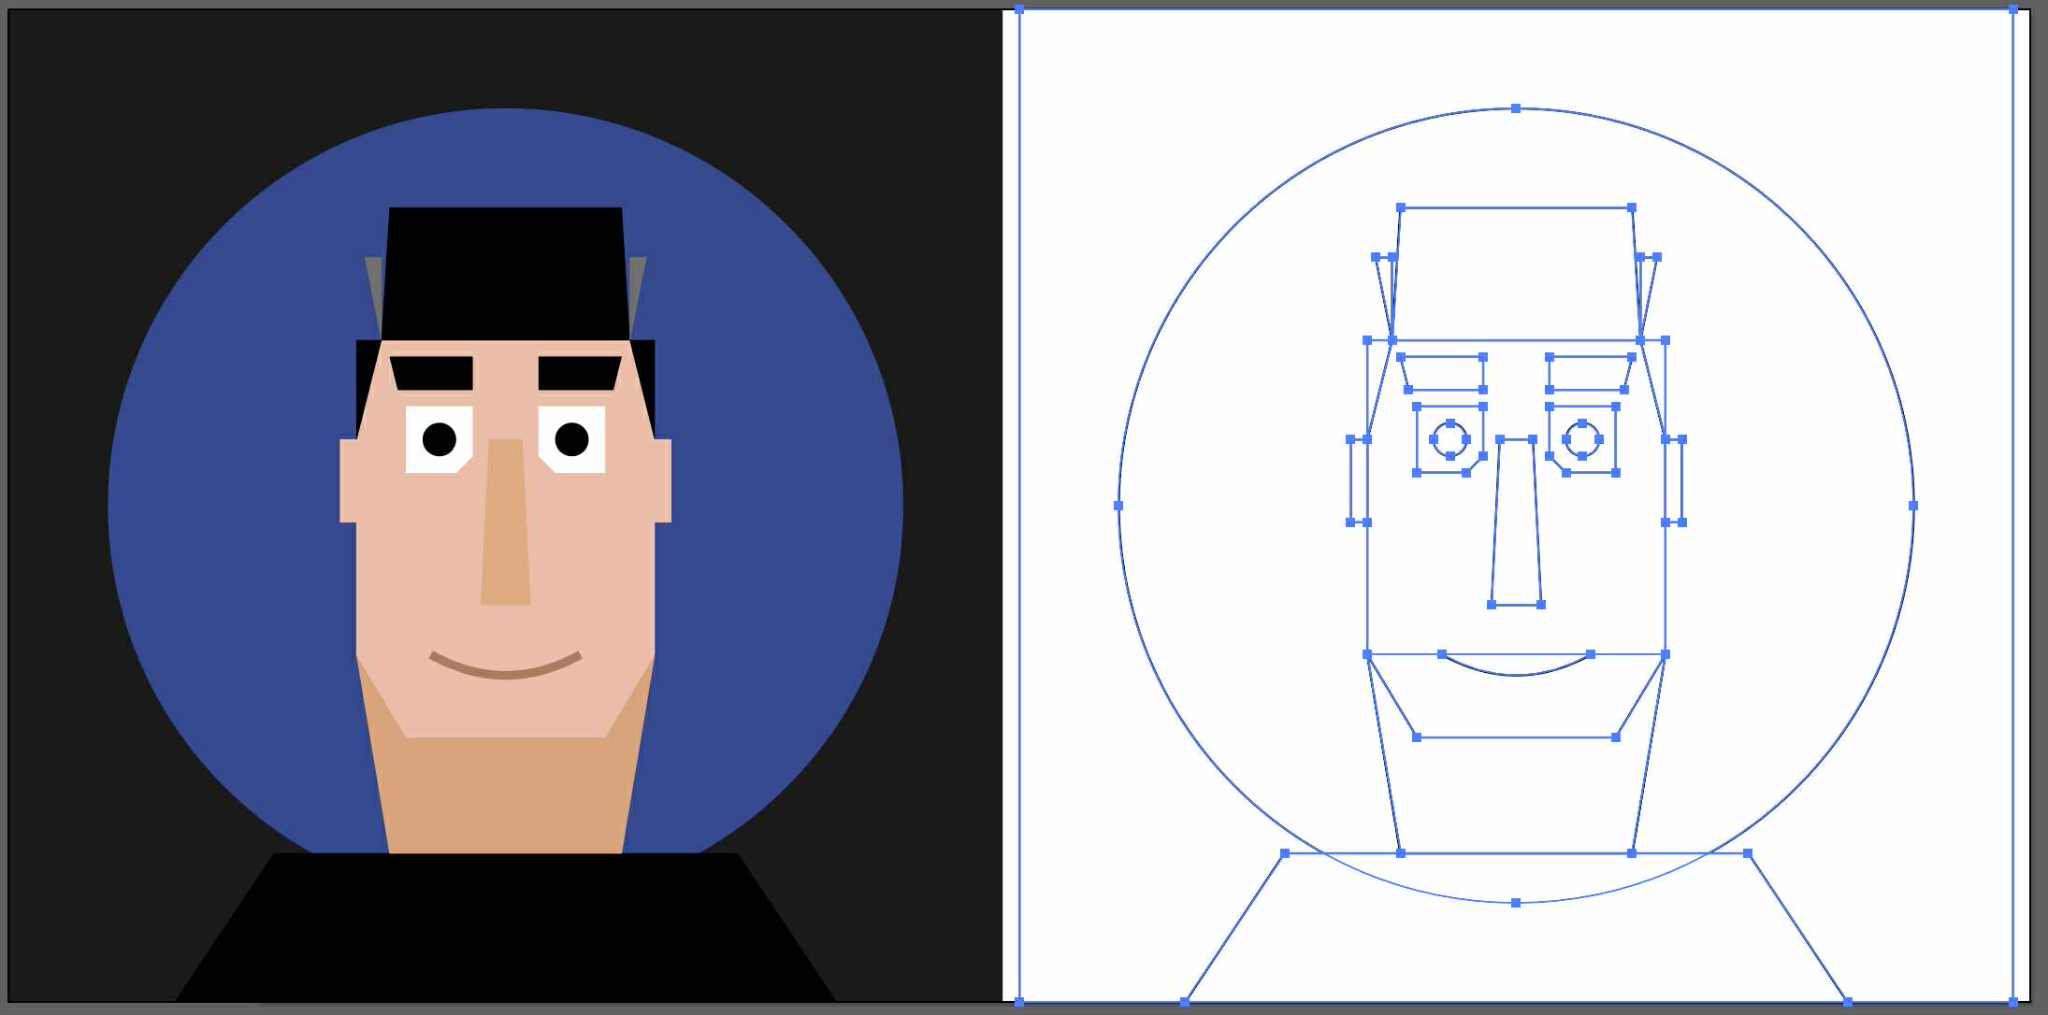
But hey, give it time. For now I love seeing the progress!
Passion is contagious, and I love when people deeply care what they’re bringing into the world. I had no idea I could find the details of fast-food chicken so interesting, but dang if founder Todd Graves’s enthusiasm doesn’t jump right off the screen. Seriously, give it a watch!
Nice clip for any product maker.
(also highlights how every business is complex when you get into the details – it is useful to remember this because many in tech give the excuse “oh, my product is complex and special” – EVERYTHING is complex and it’s your job to deal with that) https://t.co/zgd4uAsGsl
— Shreyas Doshi (@shreyas) November 16, 2025
I’m reminded of Richard Feynman’s keen observation:
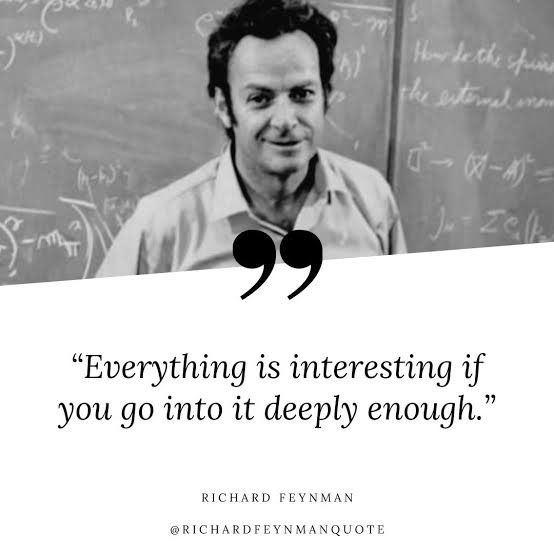
More tangentially, this gets me thinking back to my actor friends’ appreciation of Don Cheadle’s craft in this scene from Boogie Nights. “I could watch that guy pick out donuts all day!” And even though I can’t grok the work nearly as deeply as they do, I love how much they love it.
My buddy Bilawal recently sat down with Canva cofounder & Chief Product Officer Cameron Adams for an informative conversation. These points, among others, caught my attention:
00:00 – Canva’s $32B Empire the future of Design
02:26 – Design for Everyone: Canva’s Origin Story
04:19 – Why Canva Bet on the Web
07:29 – How Have Canva Users Changed Over the Years?
12:14 – Why Canva Isn’t Just Unbundling Adobe
14:50 – Canva’s AI Strategy Explained
18:12 – What Does Designing With AI Look Like?
22:55 – Scaling Content with Sheets, Data, and AI
27:17 – What is Canva Code?
29:38 – How Does Canva Fit Into Today’s AI Ecosystem?
32:35 – Why Adobe and Microsoft Should Be Worried
37:52 – Will Canva Expand Into Video Creation?
41:10 – Will AI Eliminate or Expand Creative Jobs?
“What was that?? But why??” :-p
On Friday I got to meet Dr. Fei-Fei Li, “the godmother of AI,” at the launch party for her new company, World Labs (see her launch blog post). We got to chat a bit about a paradox of complexity: that as computer models for perceiving & representing the world grow massively more sophisticated, the interfaces for doing common things—e.g. moving a person in a photo—can get radically simpler & more intentional. I’ll have more to say about this soon.
Meanwhile, here’s her fascinating & wide-ranging conversation with Lenny Rachitsky. I’m always a sucker for a good Platonic allegory-of-the-cave reference. 🙂
From the YouTube summary:
(00:00) Introduction to Dr. Fei-Fei Li
(05:31) The evolution of AI
(09:37) The birth of ImageNet
(17:25) The rise of deep learning
(23:53) The future of AI and AGI
(29:51) Introduction to world models
(40:45) The bitter lesson in AI and robotics
(48:02) Introducing Marble, a revolutionary product
(51:00) Applications and use cases of Marble
(01:01:01) The founder’s journey and insights
(01:10:05) Human-centered AI at Stanford
(01:14:24) The role of AI in various professions
(01:18:16) Conclusion and final thoughts
And here’s Gemini’s solid summary of their discussion of world models:
I’m not fully sure what this rather eye-popping little demo says about how our brains perceive reality, and thus what we can & cannot trust, but dang if it isn’t interesting:
Secret Squirrel rides again!
I was so chuffed to text my wife from the Adobe MAX keynote and report that the next-gen video editor she’d kicked off as PM several years ago has now come to the world, at least in partial form, as the new Firefly Video Editor (currently accepting requests for access). Here our pal Dave Werner provides a characteristically charming tour:
“Jesus Christ!!” — my 16yo Lego lover
View this post on Instagram
My old pal Sam is one of the most thoughtful, down-to-earth guys you’re ever likely to meet in the design community, and if you’re looking for a calm but re-energizing way to spend a couple of minutes, I think you’ll really enjoy his seven-minute talk below. I won’t spoil anything, but do trust me. 🙂
And here’s a little visual summary courtesy of NotebookLM:
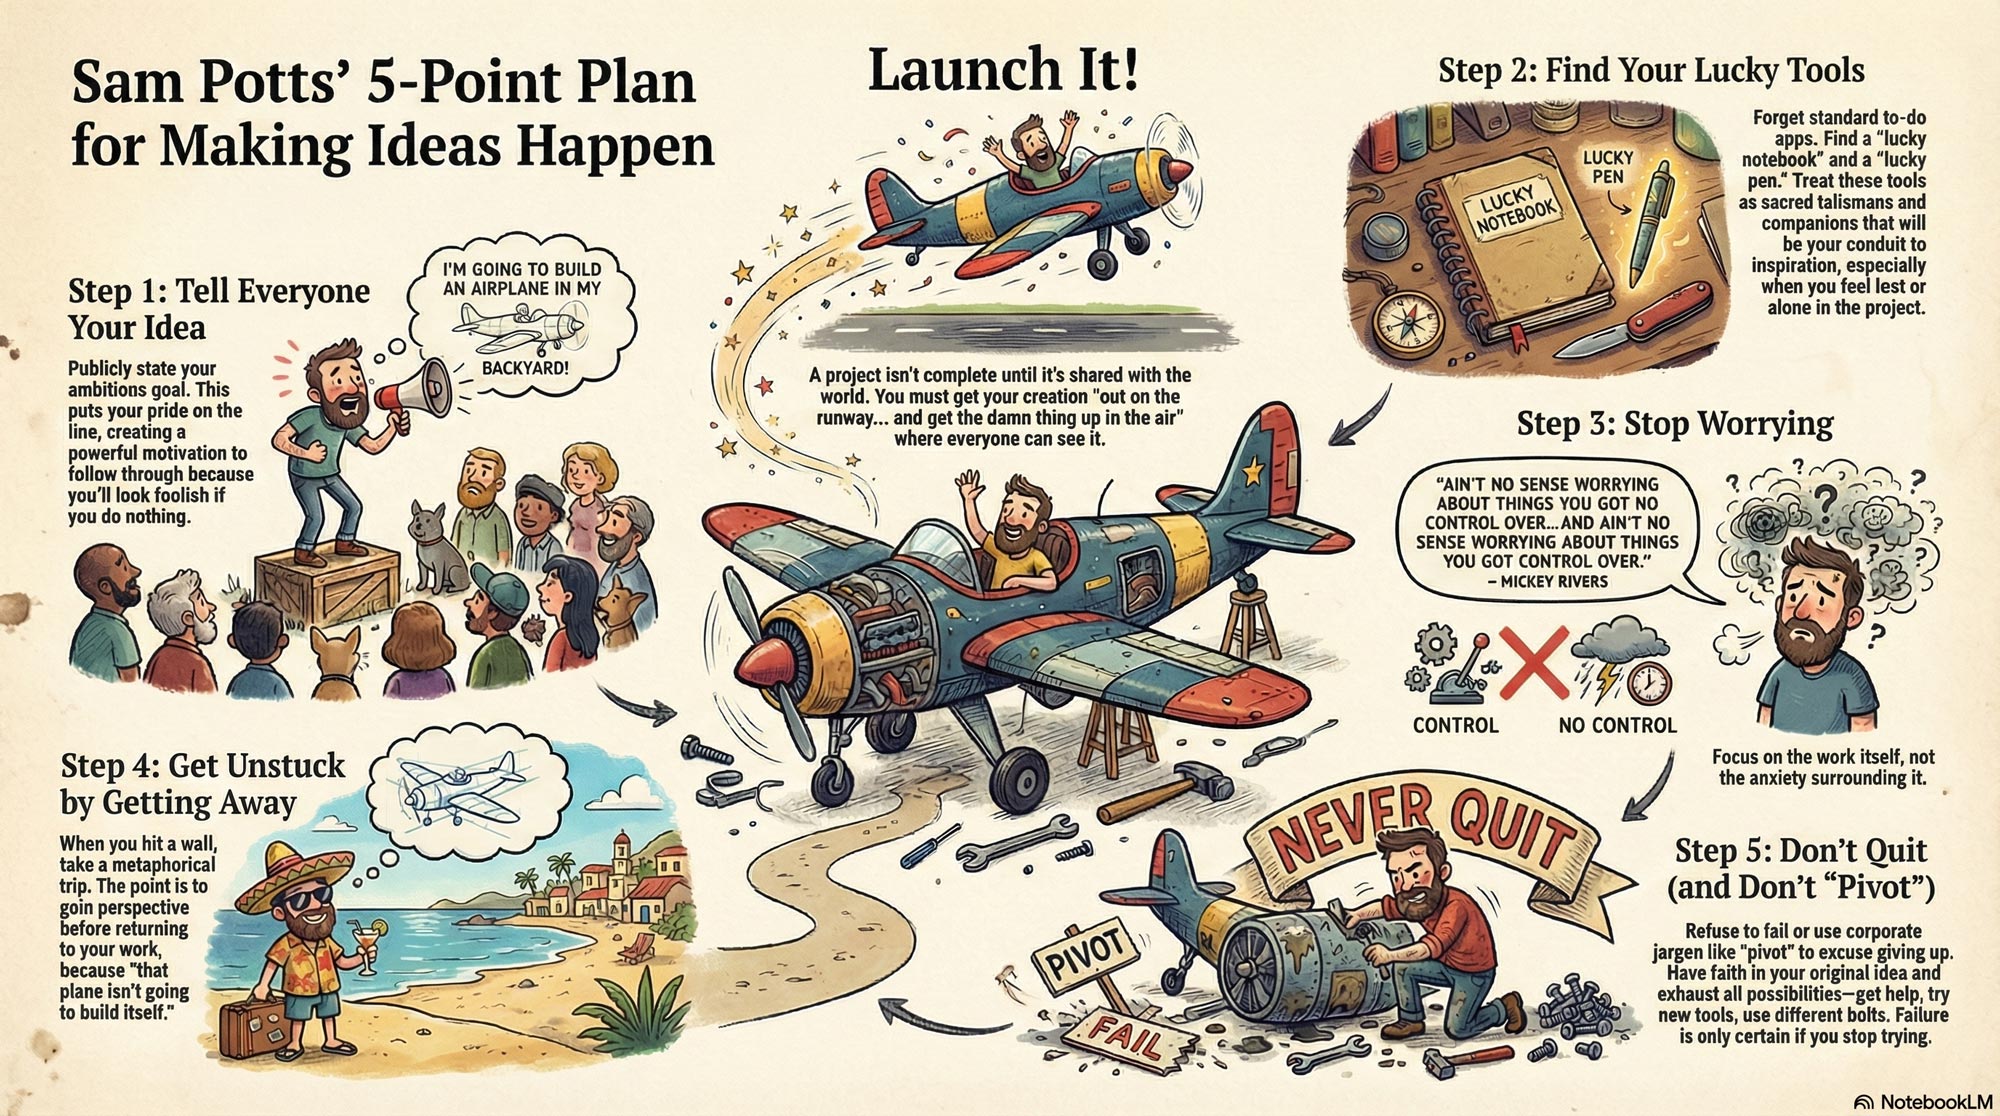
I thought this was a pretty interesting & thoughtful conversation. It’s interesting to think about ways to evaluate & reward process (hard work through challenges) and not just product (final projects, tests, etc.). AI obviously enables a lot of skipping the former in pursuit of the latter—but (shocker!) people then don’t build knowhow around solving problems, or even remember (much less feel pride in) the artifacts they produce.
The issues go a lot deeper, to the very philosophy of education itself. So we sat down and talked to a lot of teachers — you’ll hear many of their voices throughout this episode — and we kept hearing one cri du coeur again and again: What are we even doing here? What’s the point?
Links, courtesy of the Verge team:
Check out MotionStream, “a streaming (real-time, long-duration) video generation system with motion controls, unlocking new possibilities for interactive content generation.” It’s said to run at 29fps on a single H100 GPU (!).
MotionStream: Real-time, interactive video generation with mouse-based motion control; runs at 29 FPS with 0.4s latency on one H100; uses point tracks to control object/camera motion and enables real-time video editing.https://t.co/fFi9iB9ty7 pic.twitter.com/zKb9u3bj9g
— Wildminder (@wildmindai) November 4, 2025
What I’m really wondering, though, it whether/when/how an interactive interface like this can come to Photoshop & other image-editing environments. I’m not yet sure how the dots connect, but could it be paired with something like this model?
Qwen Image Multiple Angles LoRA is an exquisitely trained LoRA!˚₊‧꒰ა
Keep character and scenes consistent, and flies the camera around! Open source got there! One of the best LoRAs I’ve come across lately pic.twitter.com/1mkmCpXgIY
— apolinario (@multimodalart) November 5, 2025
Oh man, this parody of the messaging around AI-justified (?) price increases is 100% pitch perfect. (“It’s the corporate music that sends me into a rage.”)
View this post on Instagram
My friend Bilawal got to sit down with VFX pioneer John Gaeta to discuss “A new language of perception,” Bullet Time, groundbreaking photogrammetry, the coming Big Bang/golden age of storytelling, chasing “a feeling of limitlessness,” and much more.
In this conversation:
Continue reading— How Matrix VFX techniques became the prototypes for AI filmmaking tools, game engines, and AR/VR systems
— How The Matrix team sourced PhD thesis films from university labs to invent new 3D capture techniques
— Why “universal capture” from Matrix 2 & 3 was the precursor to modern volumetric video and 3D avatars
— The Matrix 4 experiments with Unreal Engine that almost launched a transmedia universe based on The Animatrix
— Why dystopian sci-fi becomes infrastructure (and what that means for AI safety)
— Where John is building next: Escape.art and the future of interactive storytelling
I’m pleased to see that as promised back in May, Photoshop has added a “Dynamic Text” toggle that automatically resizes the size of the letters in each line to produce a visually “packed” look:
Results can be really cool, but because the model has no knowledge of the meaning and importance of each word, they can sometimes look pretty dumb. Here’s my canonical example, which visually emphasizes exactly the wrong thing:
I continue to want to see the best of both worlds, with a layout engine taking into account the meaning & thus visual importance of words—like what my team shipped last year:

I’m absolutely confident that this can be done. I mean, just look at the kind of complex layouts I was knocking out in Ideogram a year ago.
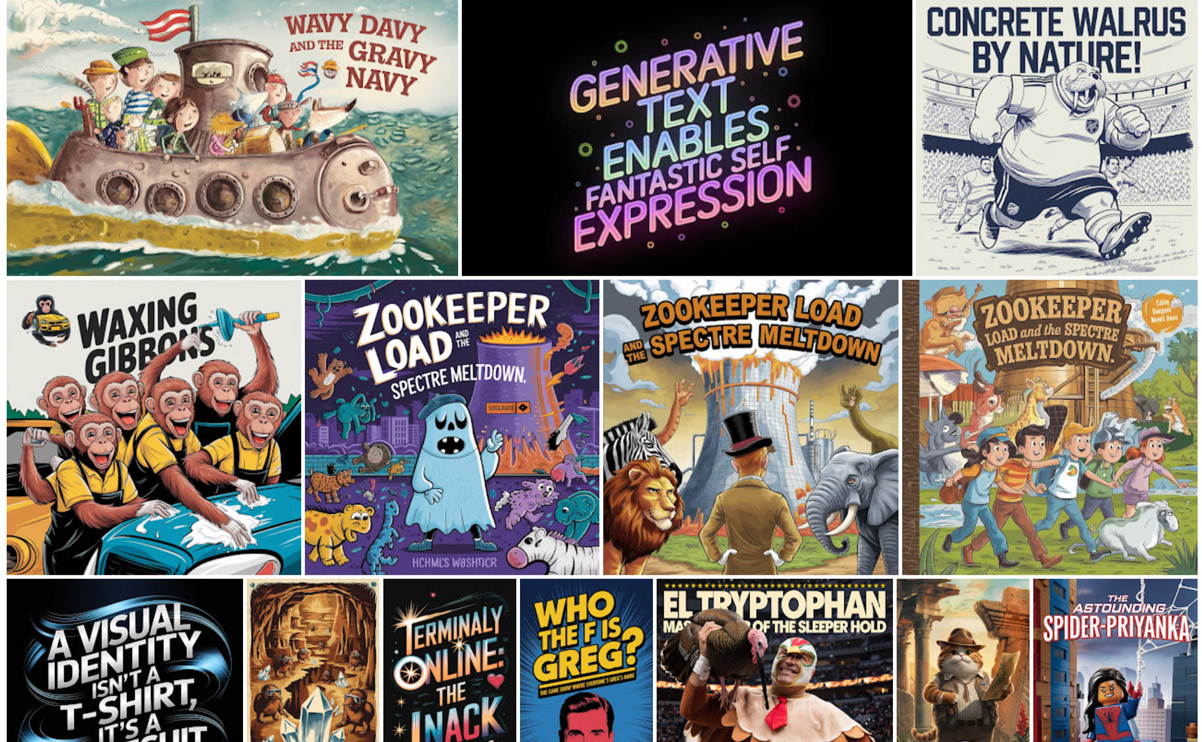
The missing ingredient is just the link between image layouts & editability—provided either by bitmap->native conversion (often hard, but doable in some cases), or by in-place editing (e.g. change “Merry Christmas” to “Happy New Year” on a sign, then regenerate the image using the same style & dimensions)—or both.
Bonus points go to the app & model that enable generation with transparency (for easy compositing), or conversion to vectors—or, again, ¿porque no los dos? 🙂
I recently shared a really helpful video from Jesús Ramirez that showed practical uses for each model inside Photoshop (e.g. text editing via Flux). Now here’s a direct comparison from Colin Smith, highlighting these strengths:
These specific examples are great, but I continue to wish for more standardized evals that would help produce objective measures across models. I’m investigating the state of the art there. More to share soon, I hope!
Improvements to imaging continues its breakneck pace, as engines evolve from “simple” text-to-image (which we considered miraculous just three years ago—and which I still kinda do, TBH) to understanding time & space.
Now Emu (see project page, code) can create entire multi-page/image narratives, turn 2D images into 3D worlds, and more. Check it out:
Can’t wait to try this out!
We’ve been thinking a lot about how generative AI can make editing feel faster, smarter, and more intuitive without losing the control creators love.
Today at #AdobeMAX, the #AdobeFirefly team previewed Layered Image Editing: bringing the power of layers and compositing together… pic.twitter.com/VVPtv9hVbK
— Alexandru Costin (@acostin) October 28, 2025
I’m down in LA having tons of great conversations around AI and the future of creativity. If you want to chat, please hit me up. firstname dot lastname at gmail.